DeepSeek V4 Pro Goes Official — Still 30x Cheaper Than Its Rivals
DeepSeek V4 Pro Goes Official — Still 30x Cheaper Than Its Rivals
DeepSeek's cheapest model beat its flagship at its own game last month, and I've been checking the API docs every evening since, waiting for the answer. On the evening of August 12, it came: DeepSeek-V4-Pro-0813 is now the live version of deepseek-v4-pro, and the eval table that shipped with it is the story — Terminal Bench 2.1 at 87.9, DeepSWE at 62.7. Those numbers don't just beat the preview; they beat Claude Opus 4.8 on both, and on Terminal Bench sit within half a point of Kimi-K3 and Fable 5. The price didn't move: $0.435 per million input tokens, $0.87 output. Put that next to GPT-5.6 Sol's $30-per-million output price and it's not a discount — it's roughly 34x cheaper.
If you missed the spring: DeepSeek previewed V4 in April as two models — V4-Pro (1.6T total parameters, 49B active, the premium tier) and V4-Flash (284B/13B, the workhorse) — both MIT-licensed, both with a 1M-token context window. Flash went official on July 31. Now Pro has followed, under the build tag 0813, with the same 1M context, 384K max output, and concurrency limits (500 for Pro vs 2500 for Flash). The one real change beyond the version tag: the official Pro now supports the Responses API, Codex-style agent integration, and the Anthropic-compatible endpoint — all Flash-only at the July 31 update. Same model ID, same endpoint, no code changes needed; the upgraded model just answers when you call deepseek-v4-pro.
DeepSeek-V4-Pro on Hugging Face (model card thumbnail; image: Hugging Face)
The official benchmarks, measured
The 0813 eval table is out, and it settles the family drama that started on July 31 — when DeepSeek promoted V4-Flash to official status and its re-post-trained build (Flash-0731) beat V4-Pro-Preview on every agentic benchmark the company publishes. DeepSWE alone went from 7.3 (Flash-Preview) to 54.4 on that re-post-training — a 7x jump from a model that costs $0.14/$0.28. The obvious question: if the cheap model beats the expensive one, what is Pro for?
The official build is the answer, and this time the numbers shipped with the release.
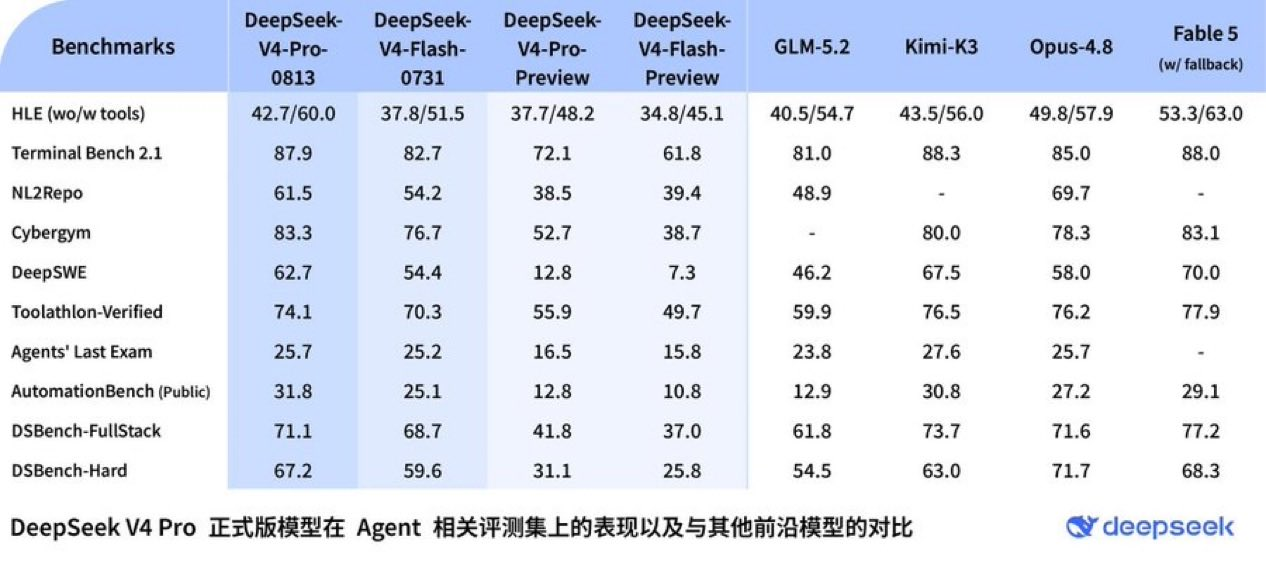
DeepSeek's official agentic eval table for V4-Pro-0813 (image: DeepSeek; vendor-reported)
| Benchmark | V4-Pro-0813 | V4-Flash-0731 | V4-Pro-Preview | GLM-5.2 | Kimi-K3 | Opus-4.8 | Fable 5 |
|---|---|---|---|---|---|---|---|
| Terminal Bench 2.1 | 87.9 | 82.7 | 72.1 | 81.0 | 88.3 | 85.0 | 88.0 |
| NL2Repo | 61.5 | 54.2 | 38.5 | 48.9 | — | 69.7 | — |
| Cybergym | 83.3 | 76.7 | 52.7 | — | 80.0 | 78.3 | 83.1 |
| DeepSWE | 62.7 | 54.4 | 12.8 | 46.2 | 67.5 | 58.0 | 70.0 |
| Toolathlon-Verified | 74.1 | 70.3 | 55.9 | 59.9 | 76.5 | 76.2 | 77.9 |
| AutomationBench (Public) | 31.8 | 25.1 | 12.8 | 12.9 | 30.8 | 27.2 | 29.1 |
| HLE (with tools) | 60.0 | 51.5 | 48.2 | 54.7 | 56.0 | 57.9 | 63.0 |
Agentic benchmarks from the official V4-Pro-0813 release (DeepSeek-reported; Fable 5 evaluated with Anthropic's fallback harness)
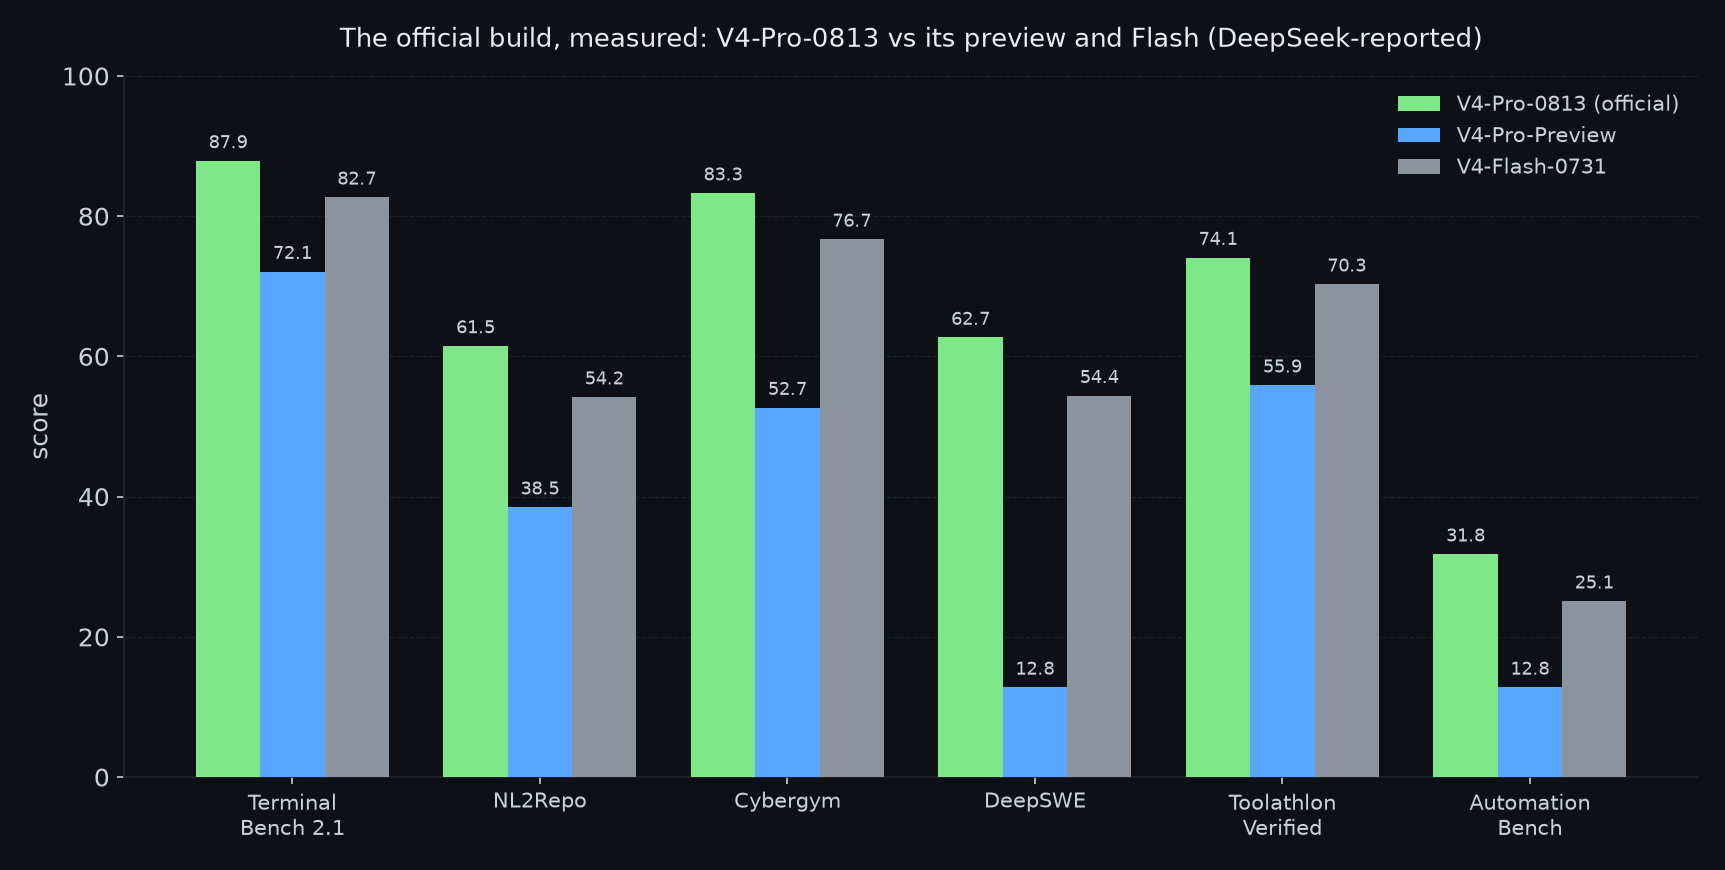
The official build, measured: V4-Pro-0813 vs its preview and Flash across six agentic evals
The numbers tell a clean story. Versus its own preview, the official build is a different model: Terminal Bench 2.1 jumps 72.1 → 87.9, DeepSWE goes 12.8 → 62.7, AutomationBench 12.8 → 31.8. Versus the frontier, it sits right in the middle of the pack — it beats Claude Opus 4.8 on Terminal Bench (87.9 vs 85.0) and DeepSWE (62.7 vs 58.0), and matches Fable 5 on Cybergym (83.3 vs 83.1). The only leads against it: Kimi-K3, Fable 5, and Opus-4.8 (on NL2Repo and Toolathlon-Verified). The "open-weight model trades blows with the frontier" story is no longer just about price; the official build's scores put it in the same conversation on the board.
The price gap, drawn to scale
Put V4 Pro next to the models people actually know and the numbers stop looking like a discount and start looking like a different category:
| Model | Input $/1M | Output $/1M | Output vs V4 Pro |
|---|---|---|---|
| DeepSeek V4 Pro | $0.435 | $0.87 | — |
| GPT-5.6 Sol | $5 | $30 | 34x |
| Claude Opus 5 | $5 | $25 | 29x |
| Fable 5 | $10 | $50 | 57x |
List prices per 1M tokens, August 2026
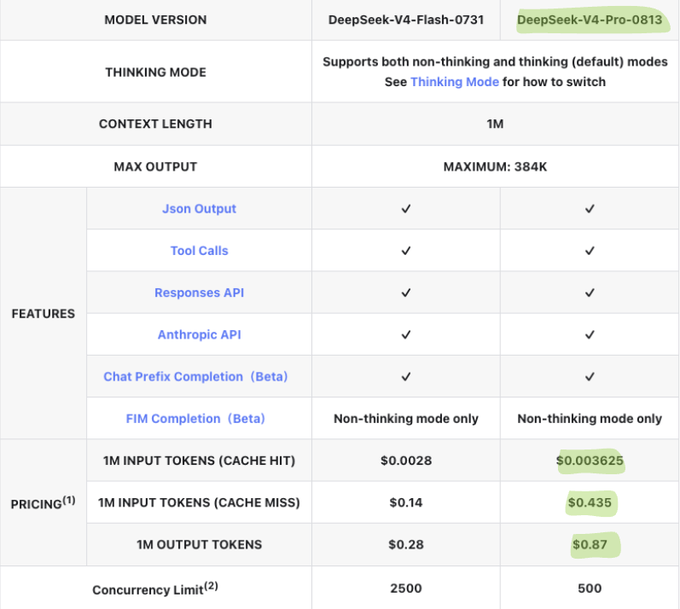
The official pricing page — Pro-0813 alongside Flash-0731, same rate card as the preview (image: DeepSeek)
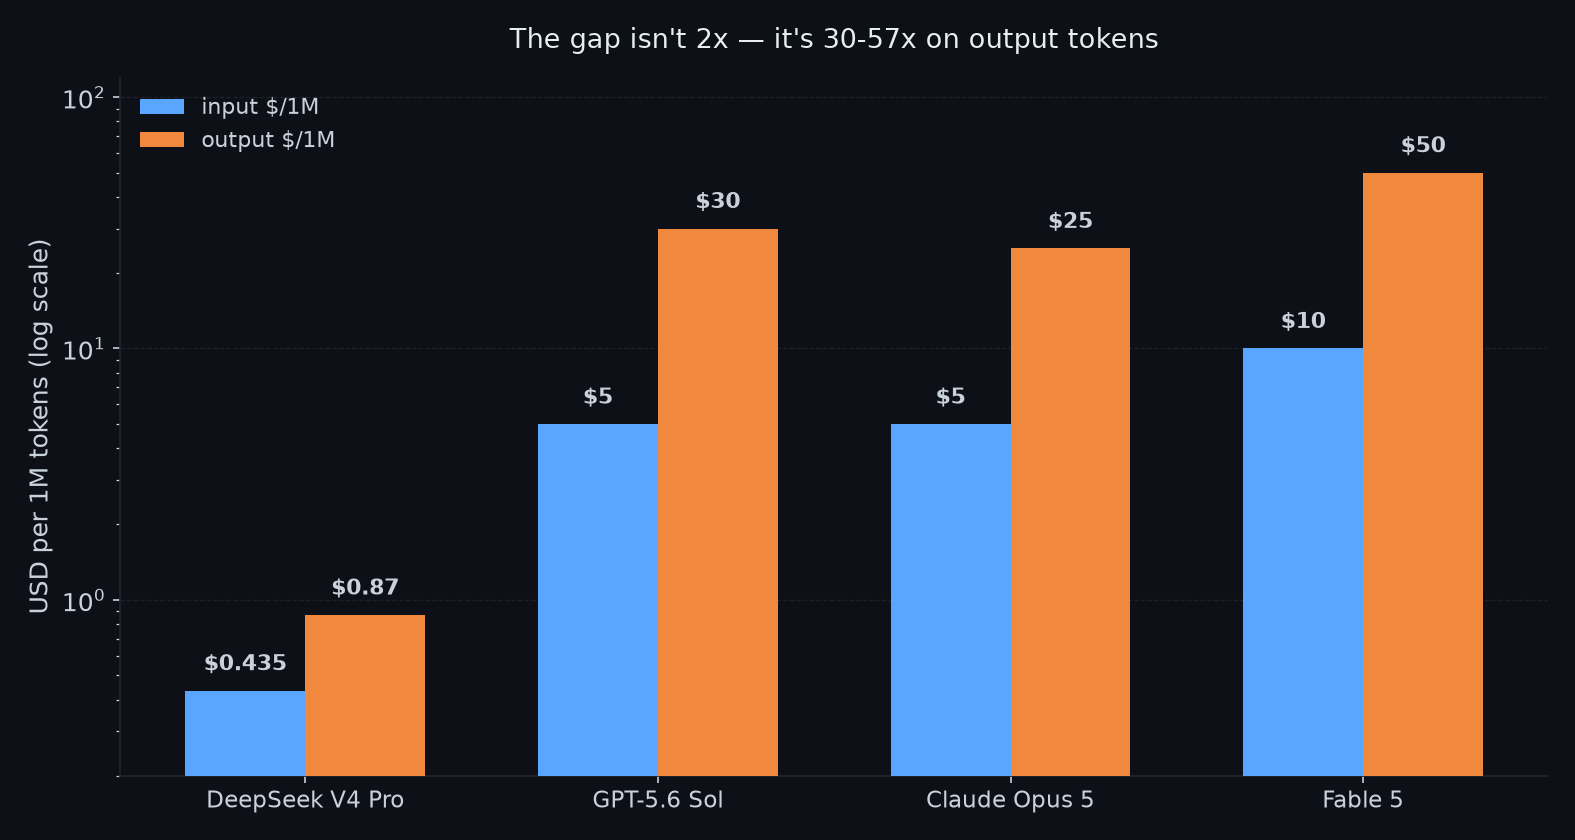
The gap isn't 2x — it's 30-57x on output tokens (log scale, list prices Aug 2026)
Cache hits make it even more lopsided: V4 Pro's cached input runs at $0.003625/1M. At these rates, a dollar of V4 Pro output goes roughly 57x further than a dollar of Fable 5. DeepSeek has been running this playbook since R1 — open weights, MIT license, prices that look like they're from a decade ago — and the official 0813 build keeps the pricing exactly where the preview left it. Worth noting: the API docs now carry a notice that DeepSeek plans a significant price increase in the near future. If you've been waiting to wire V4 Pro into a pipeline, the current rate card may not last.
The weights question
One loose end: the 0813 checkpoint hasn't appeared on Hugging Face yet. The preview weights were always MIT and freely downloadable (~865GB for Pro), and DeepSeek shipped Flash-0731 weights the same day Flash went official — so there's a reasonable expectation Pro's will follow. But as of writing, the 0813 repo isn't up. Until it lands, "open weights" officially means the preview build, and the production-grade agent numbers above live on DeepSeek's API only.
My take
Here's my honest read: the price story is real, and the benchmark story just caught up to it. A frontier-adjacent model at $0.435/$0.87 — 30x cheaper than Opus 5 and 34x cheaper than GPT-5.6 Sol, 57x cheaper than Fable 5 on output. Add MIT weights once the 0813 checkpoint drops (assuming it ships under the same license as the preview), real agent-harness support, and official scores that beat Opus 4.8 on five of the seven agentic evals. That's a genuine production option for cost-sensitive teams. That's not marketing; the rate card and the eval table are both right there.
But I can't pretend everything's settled. Every number above is DeepSeek's own measurement — the Fable 5 row runs on Anthropic's fallback harness, and no independent leaderboard has weighed in yet. The 0813 build needs to hold up outside its own changelog; until then, the "just use Flash" crowd has a point on price, and the "Pro is the flagship answer" crowd has a point on the board. Treat the April-to-August jump as real but directional — same self-reported caveat as Flash-0731.
One last thing, and it's the part that actually made me check the docs twice: prices are going up significantly, and soon. If V4 Pro at current rates fits your workload, the window is probably now. If you're comparing against Claude Opus or GPT-5.6 for a long-context agent pipeline, this is the cheapest serious test you'll run all year.
The 0813 benchmarks landed with the release — what's still pending is the weights repo, the independent leaderboards, and a date for that price increase. I'll update this post as they land (or don't). Until then, the model to watch this week isn't the flashiest one, it's the one that costs $0.87, just went into production, and put serious numbers on the board next to models at 30x the price.
Related on this blog: Gemini 3.7 Flash: Half the Price, Still No 3.5 Pro · DeepSeek Added Vision to Flash. The Text Scores Went Up.
Comments
Post a Comment