GLM-5.2's Reseller Discount: Check the Route and Date
MODELS & COSTS
GLM-5.2's Reseller Discount: Check the Route and Date
A reseller's discounted GLM rate can make a trial much cheaper than the official launch price. It does not change the model's weights or lock that price in. The August comparison below keeps the provider, cache assumptions and allowance limits beside the saving.
In this article
The June release and reported evaluations
GLM-5.2 came out June 16 as an open-weight (MIT) reasoning model with a 1M-token context window — 753B parameters, 40B active. The reception was not lukewarm. Hacker News had a thread literally titled "GLM 5.2 beats Claude in our benchmarks", independent testers found it winning four of five practical building tasks against Claude Opus 4.8, and the model card numbers backed the noise up:
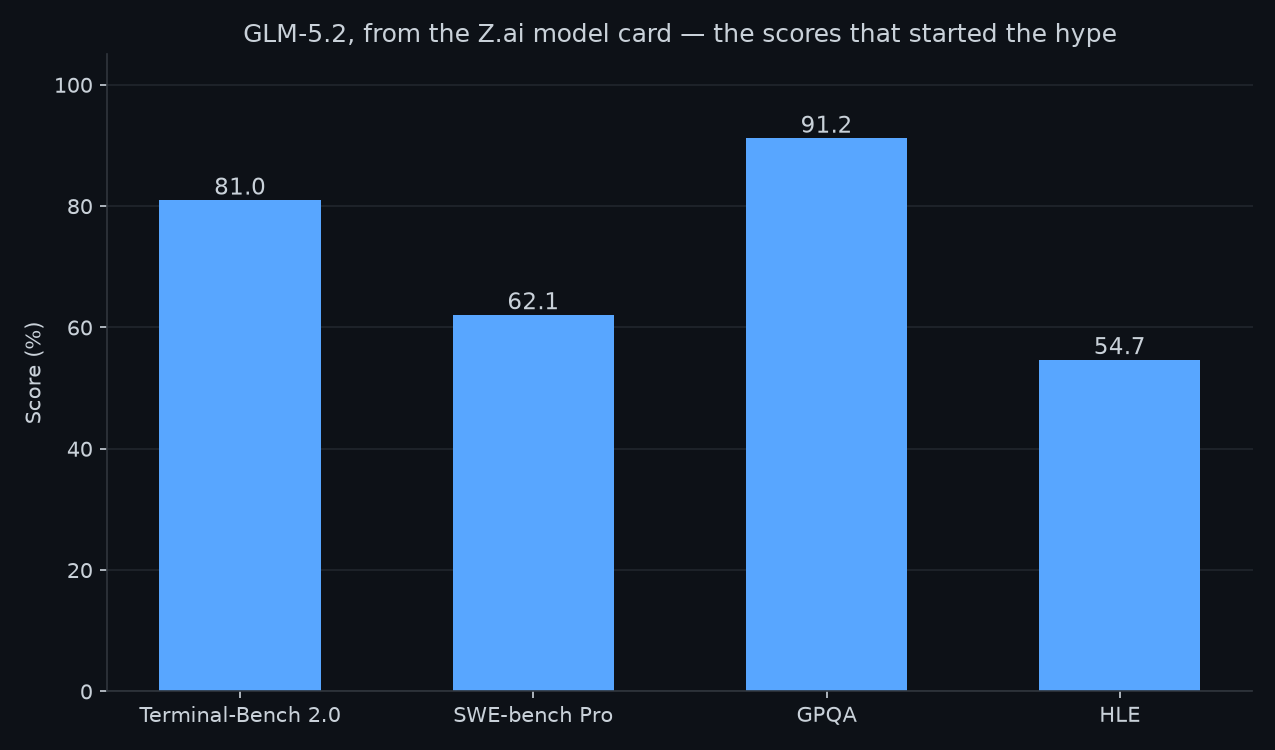
For a model you could self-host, with weights you could actually download, that was a statement. The community was excited — this felt like the point where open-weight caught up to the closed frontier.
The launch API rate
Z.ai's official API rate was $1.40 per million input tokens, $4.40 output. Not absurd by frontier standards — but this was an open-weight model competing in a market where the cheap tier had trained everyone to expect single-digit prices. The reaction split cleanly down the middle: subscription users got the $18-$65/month GLM Coding Plan and mostly shrugged happily ("Z.ai doesn't use token-based pricing in its subscription system, which works to my advantage lol" — actual Reddit quote), while API users grumbled. One HN commenter on the $65 Pro tier said the weekly limits ran out "somewhat fast" and that quota multipliers (3x during peak hours) were getting worse after September.
The verdict that stuck was a Reddit thread title: "GLM 5.2 looks strong — but does the price gap still make sense?" Strong model, wrong price for what it was. That's where the story sat for two months.
The August 10 reseller rate
OpenRouter doesn't set these discounts — the providers on it do. And sometime in the last few weeks, three hosting companies decided GLM-5.2 traffic was worth losing money on:
- StreamLake — 95% off: $0.07 in / $0.22 out (official: $1.40 / $4.40)
- NovitaAI — 94% off: $0.08 in / $0.26 out
- Baidu Qianfan — 92% off: $0.11 in / $0.35 out
- Decart — 40% off: $0.72 / $1.80, for contrast
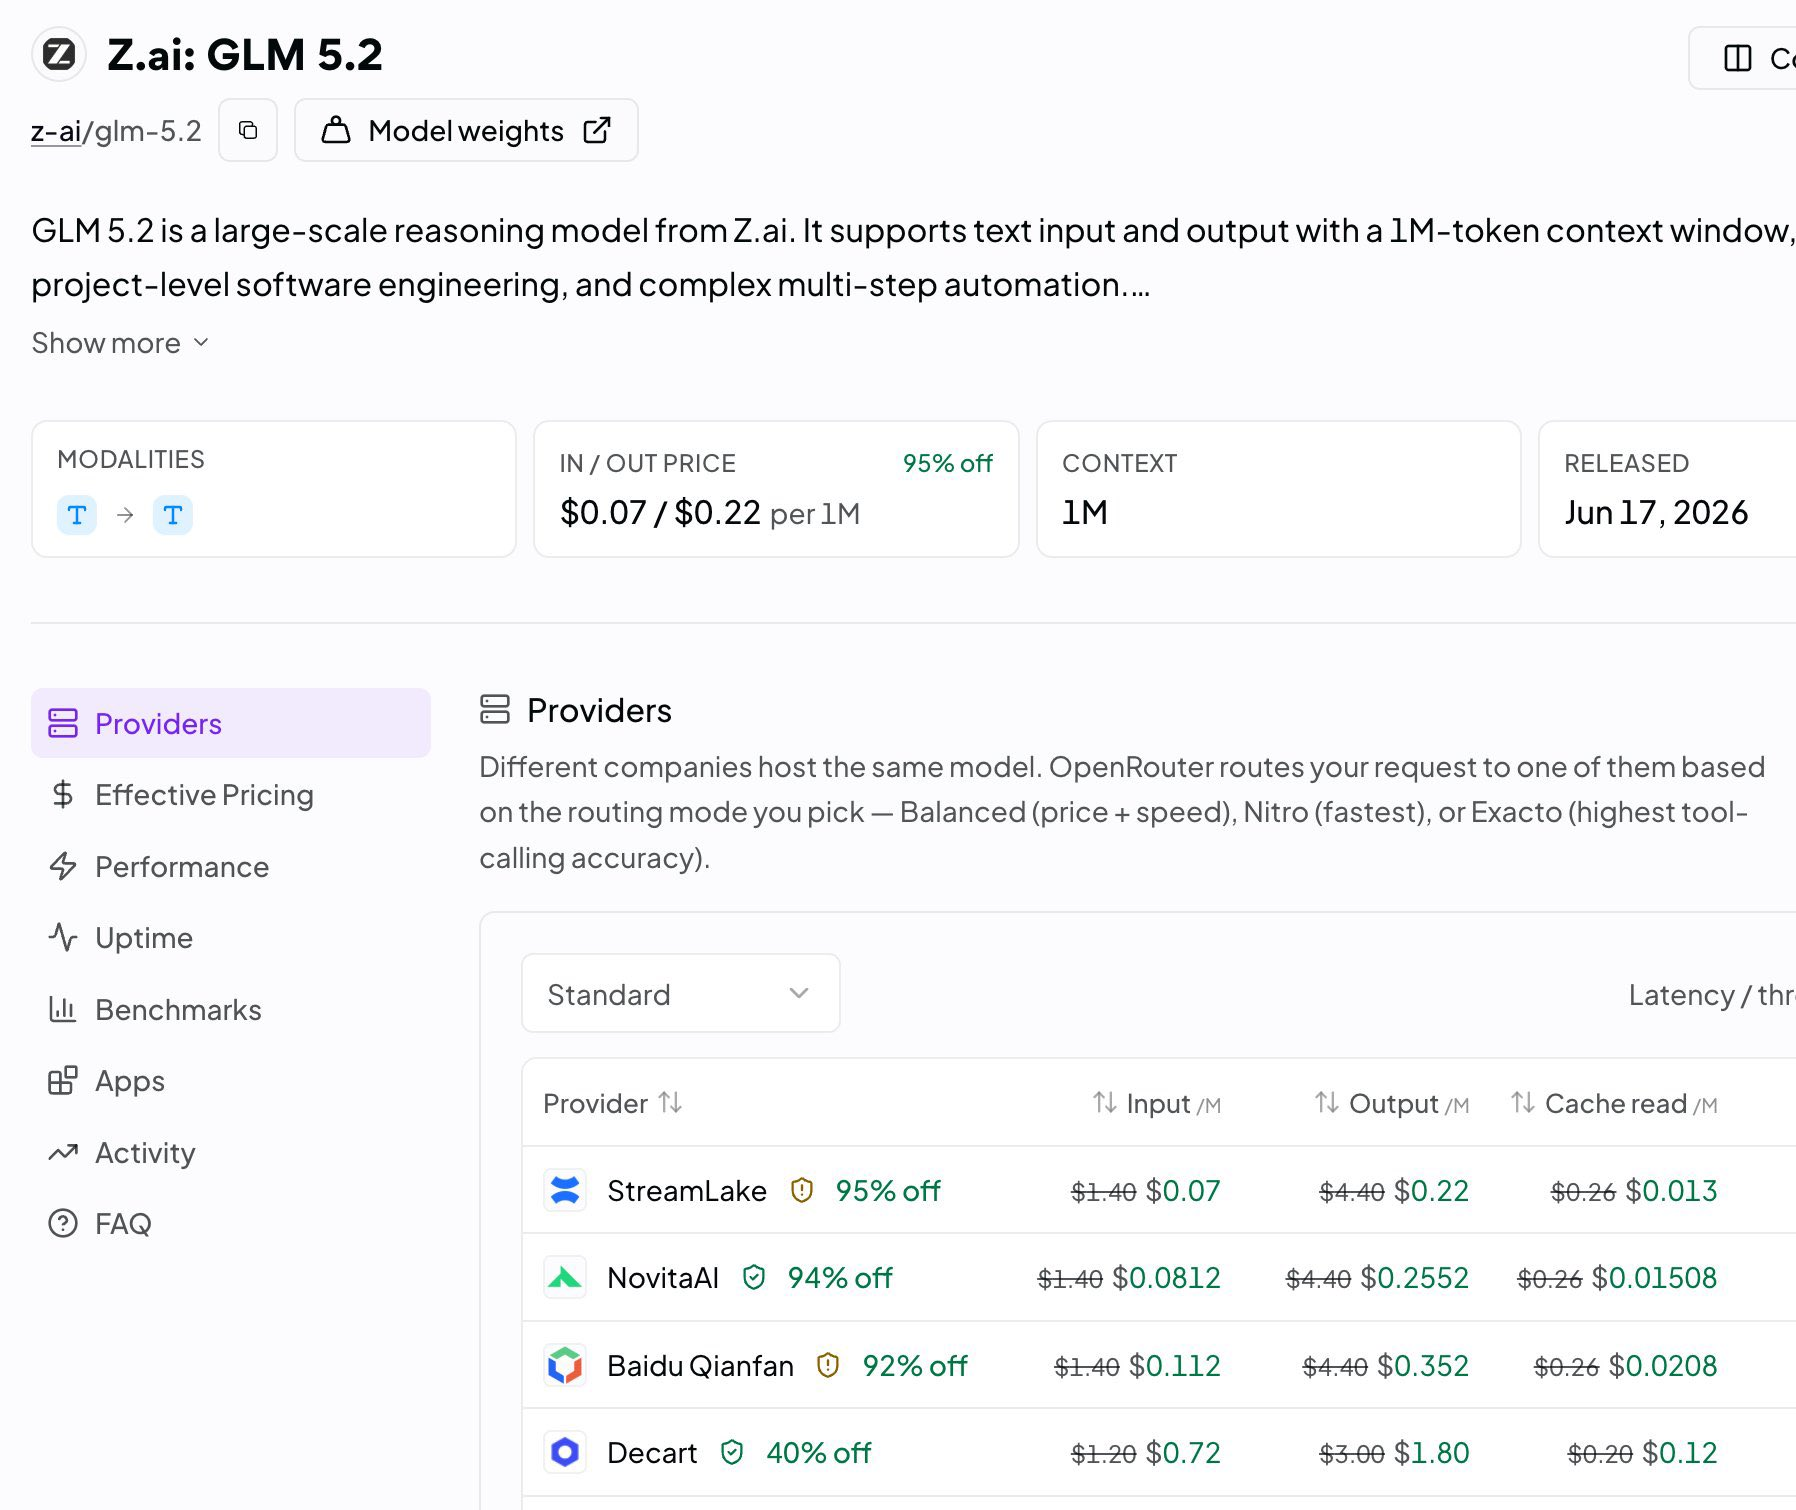
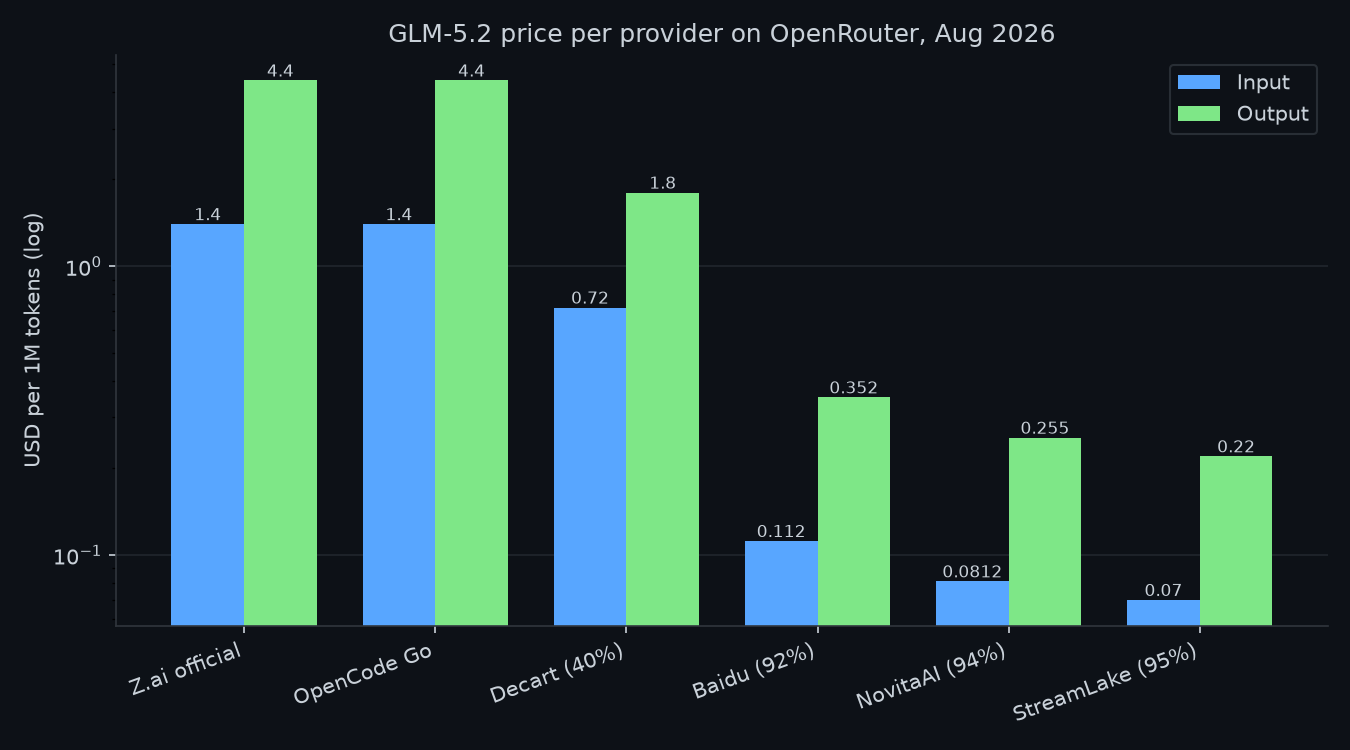
Cache reads got cut the same way — $0.013 per million at StreamLake, 95% off — which is the number that matters for agent loops that re-send context every turn. The June complaint was "great model, meh price." The August question is: does this fix it?
Workload cost at the discounted rate
Let's put a real workload on it: 100 million input tokens a month, 20 million output, half the input hitting cache — a normal agent-session pattern:
| Route | Monthly cost |
|---|---|
| OpenRouter via StreamLake (95% off) | ~$8.55 |
| OpenRouter via NovitaAI (94% off) | ~$9.92 |
| OpenRouter via Baidu (92% off) | ~$13.68 |
| OpenCode Go subscription — GLM-5.2 at full rate | $10 flat, capped at $60 usage/mo (~35% of this workload) |
| Z.ai official API (no discount) | ~$171 |
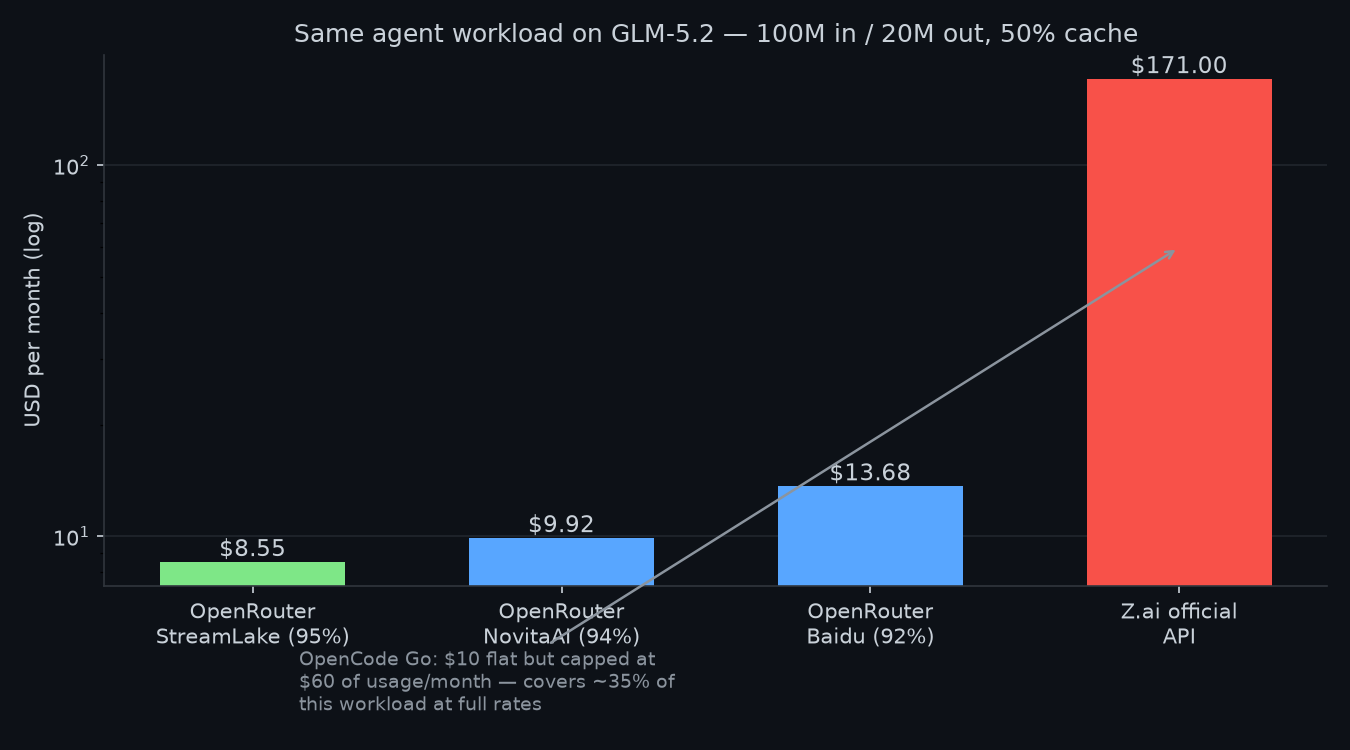
At the cited $0.07 input and $0.22 output rates per million tokens, GLM-5.2 becomes a lower-cost candidate for API trials. The actual bill depends on provider routing, cache treatment, reasoning tokens and whether tasks finish successfully. The discount alone does not establish the best value across models.
One row deserves extra explanation: OpenCode Go's $10 flat sounds like the cheapest row, but GLM-5.2 there is billed at the full official rate inside a $60/month usage cap (about 4,300 requests). My workload — 50M fresh + 50M cached input, 20M output — comes to ~$171 of usage at those rates, so the subscription covers roughly a third of it before you hit the wall. The 95%-off price exists only on OpenRouter's discounted providers. Same for the Coding Plan: Z.ai's own subscription doesn't get cheaper either.
But two asterisks. First, the discount lives on OpenRouter's providers, not on Z.ai's own rate card — the official API still charges $1.40/$4.40, so this helps API users who route through OpenRouter. Second, this is a provider price war, not a Z.ai announcement: there's no end date, and there's also no guarantee. More on that below.
Four pricing caveats
1. The discount is a provider decision, not a law of nature. StreamLake, NovitaAI and Baidu are fighting for OpenRouter traffic — that's the whole reason this exists. No end date on the page, but no contract either. Provider prices change without notice; that's how this market has always worked. I'd bet on the war lasting (three competitors, one model, 20x spread), but "bet" is the operative word.
2. Reasoning tokens balloon. GLM-5.2 is a reasoning model and 'high'/'xhigh' effort burns output tokens fast. At $0.22/M output that's still cheap, but your bill can double or triple versus what input-price math suggests. Watch actual output volume, not just the rate.
3. The cache discount is OpenRouter-specific. Z.ai's own API charges full price on cached input. The 95%-off cache read exists only on these providers — route elsewhere and the economics change.
4. The Coding Plan crowd gets nothing from this. Subscribers already had their flat-rate deal; this discount is aimed at API traffic. If you're on the $18-65/month plan, your calculus doesn't move.
Before switching providers
For the example workload below, the discounted rate produces the stated monthly estimate. That estimate is not an $8 subscription and should not be treated as a universal agent budget. Recalculate it with your token mix and a current provider quote before changing a workflow.
A small comparison against the existing provider should include latency, retries, tool-call success and total billed usage. Keep the tested provider and date in the result; a reseller's rate can change independently of the official API.
Prices checked Aug 10, 2026. Launch reactions: Hacker News (item 48709670, 48714425), r/artificial, r/AISEOInsider, r/ZaiGLM. Model card scores: Z.ai official. OpenCode Go limits: opencode.ai/docs/go. Costs assume 100M input / 20M output / 50% cache-hit per month at listed rates.
Related on this blog: Astra: 10 Math Proofs, Then OpenAI Paused Its Own Model · 96% to 11%: GLM-5.3-Flash, Uncensored at the Weight Level
Comments
Post a Comment