Grok 4.6: The Published Tasks Behind the Price Claim
MODELS & COSTS
Grok 4.6: The Published Tasks Behind the Price Claim
Grok 4.6's post-training update targets longer agent work at lower listed rates than the rivals cited here. The vendor's aggregate score hides a mixed set of rows. A migration trial should start with the difficult tasks your current model fails, not with the headline average.
In this article
So what is 4.6, exactly? A post-training refresh of Grok 4.5 — not a bigger brain, a better-behaved one. SpaceXAI focused the release on long-running agents and ambitious interactive work: staying with complex tasks across many steps, researching unfamiliar domains, structuring an app and iterating on it. The company says it now hits 61 on the Artificial Analysis Intelligence Index, tying GPT-5.6 Sol (61) and sitting one point behind Fable 5 (62). Grok 4.5 scored 56.
Grok 4.6 — announced August 12, 2026 (image: SpaceXAI / X)
The vendor evaluation card
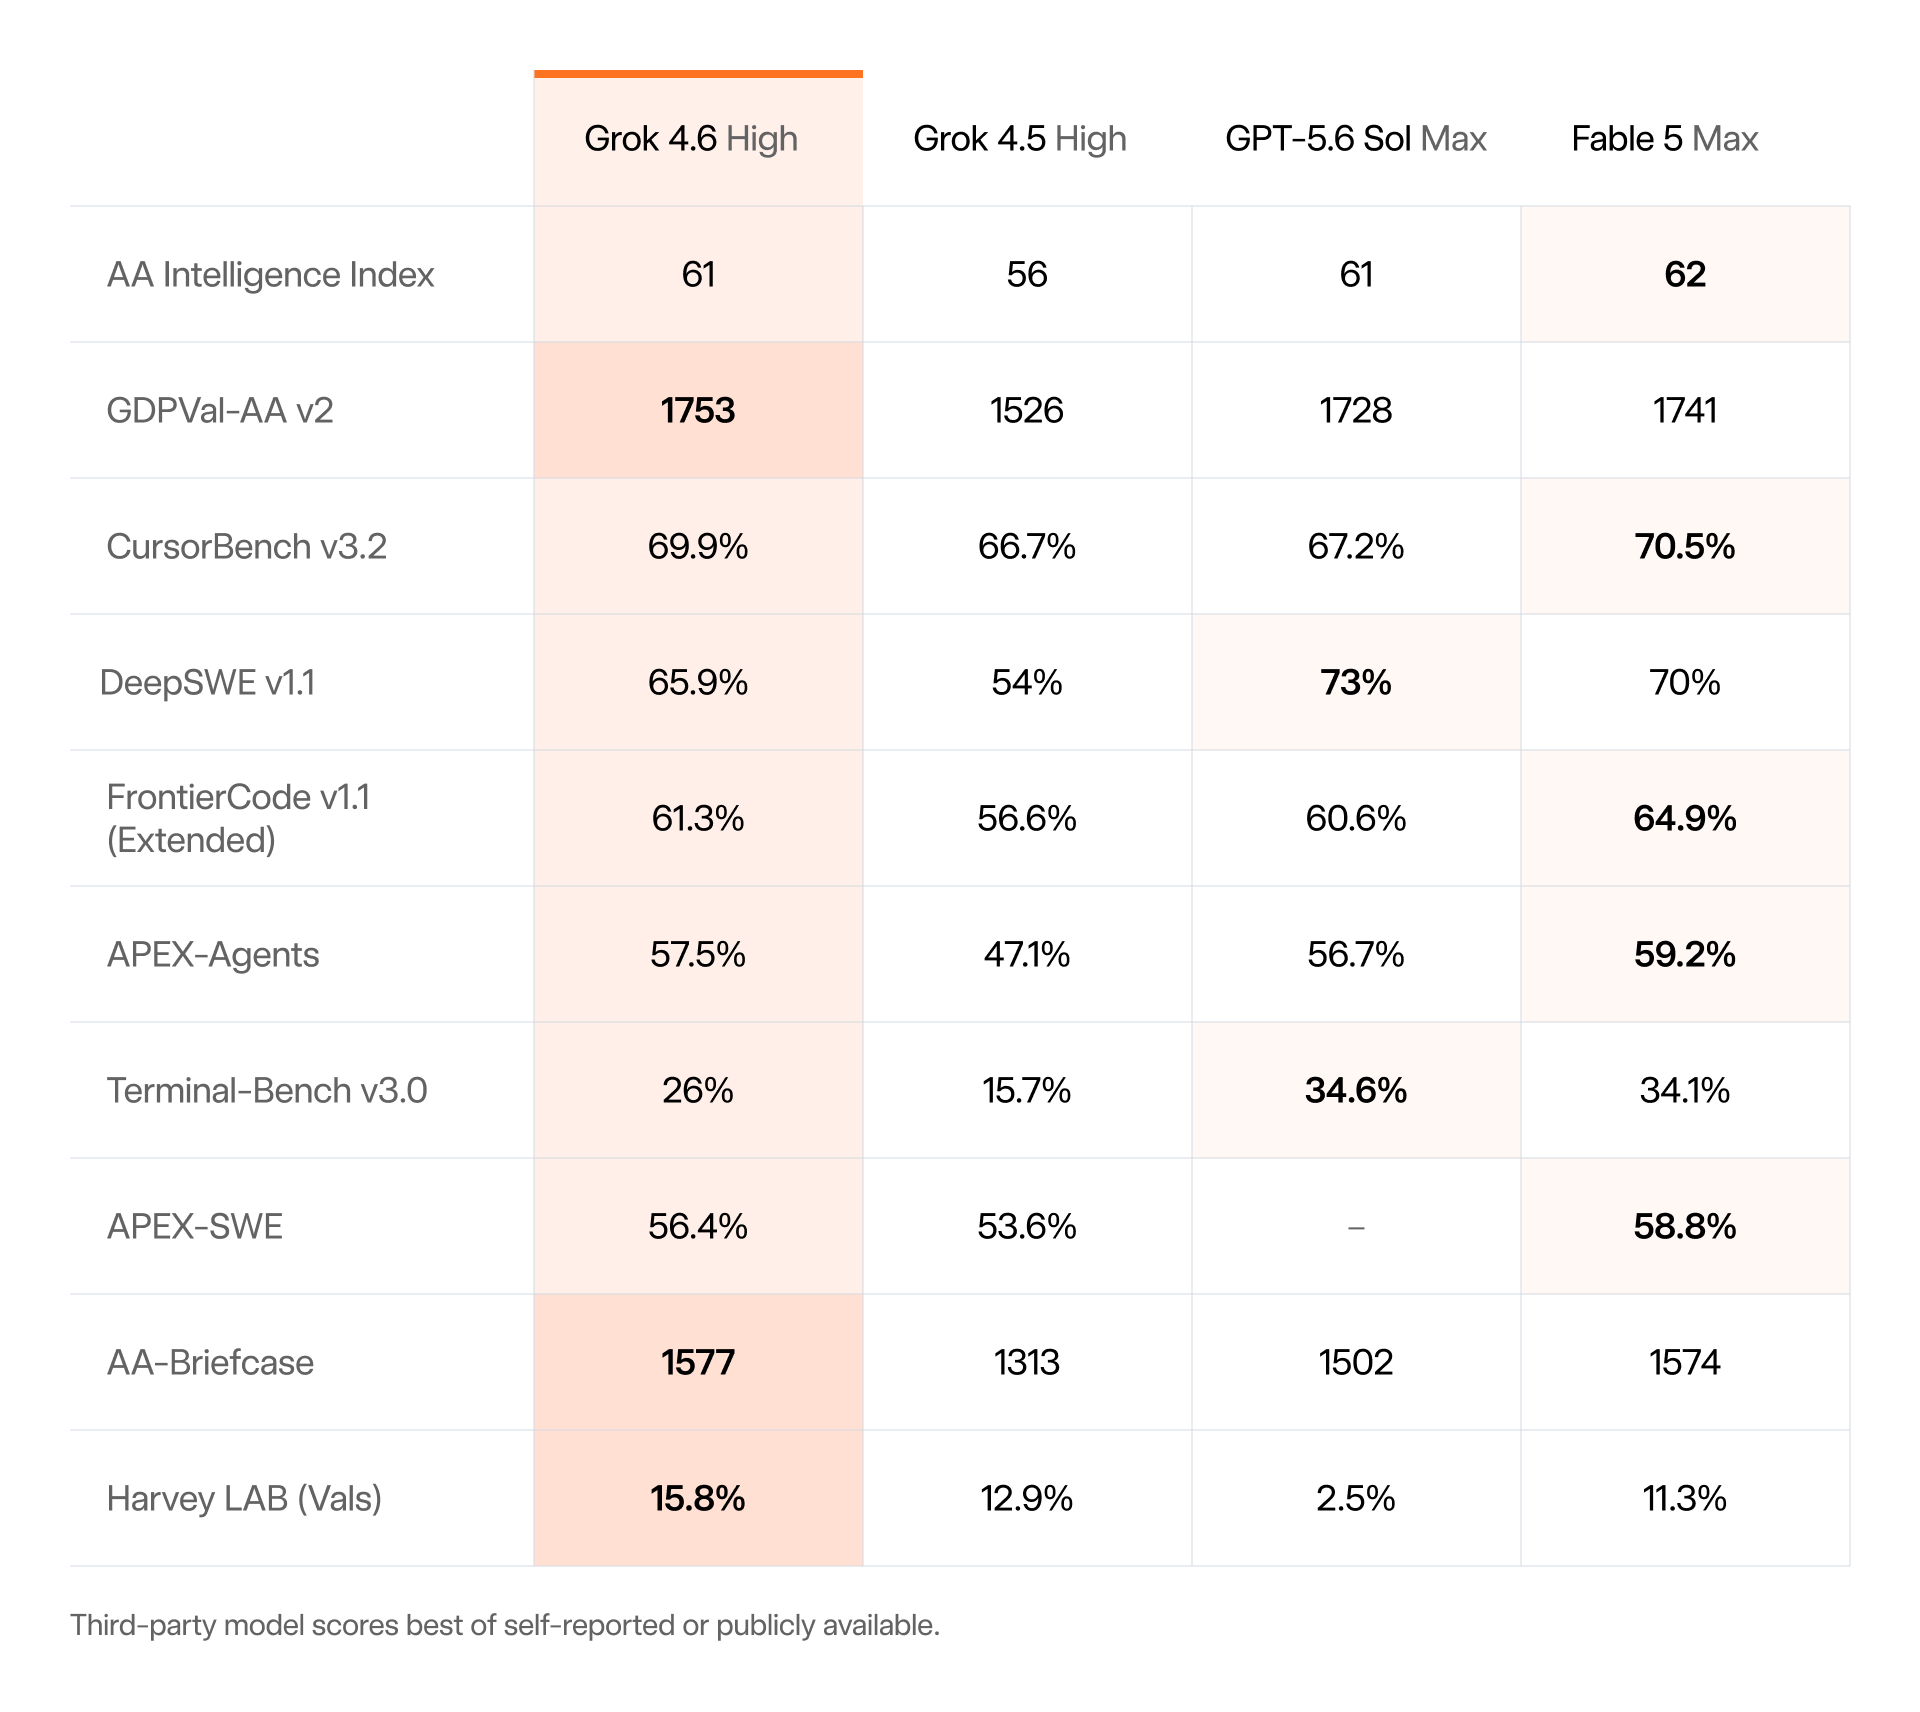
Here's the full table from the launch post. Every number is vendor-reported — SpaceXAI's own runs, with competitor figures drawn from their published system cards — so treat it as the company's best case, not an independent verdict:
| Benchmark | Grok 4.6 | Grok 4.5 | GPT-5.6 Sol | Fable 5 |
|---|---|---|---|---|
| AA Intelligence Index | 61 | 56 | 61 | 62 |
| GDPVal-AA v2 | 1753 | 1526 | 1728 | 1741 |
| CursorBench v3.2 | 69.9% | 66.7% | 67.2% | 70.5% |
| DeepSWE v1.1 | 65.9% | 54% | 73% | 70% |
| FrontierCode v1.1 (Extended) | 61.3% | 56.6% | 60.6% | 63.6% |
| APEX-Agents | 57.5% | 47.1% | 56.7% | 59.2% |
| Terminal-Bench v3.0 | 26% | 15.7% | 34.6% | 34.1% |
| Harvey LAB (Vals) | 15.8% | 12.9% | 2.5% | 11.3% |
| APEX-SWE | 56.4% | 53.6% | — | 58.8% |
Selected evals from the Grok 4.6 launch post (vendor-reported; best score per row in green)
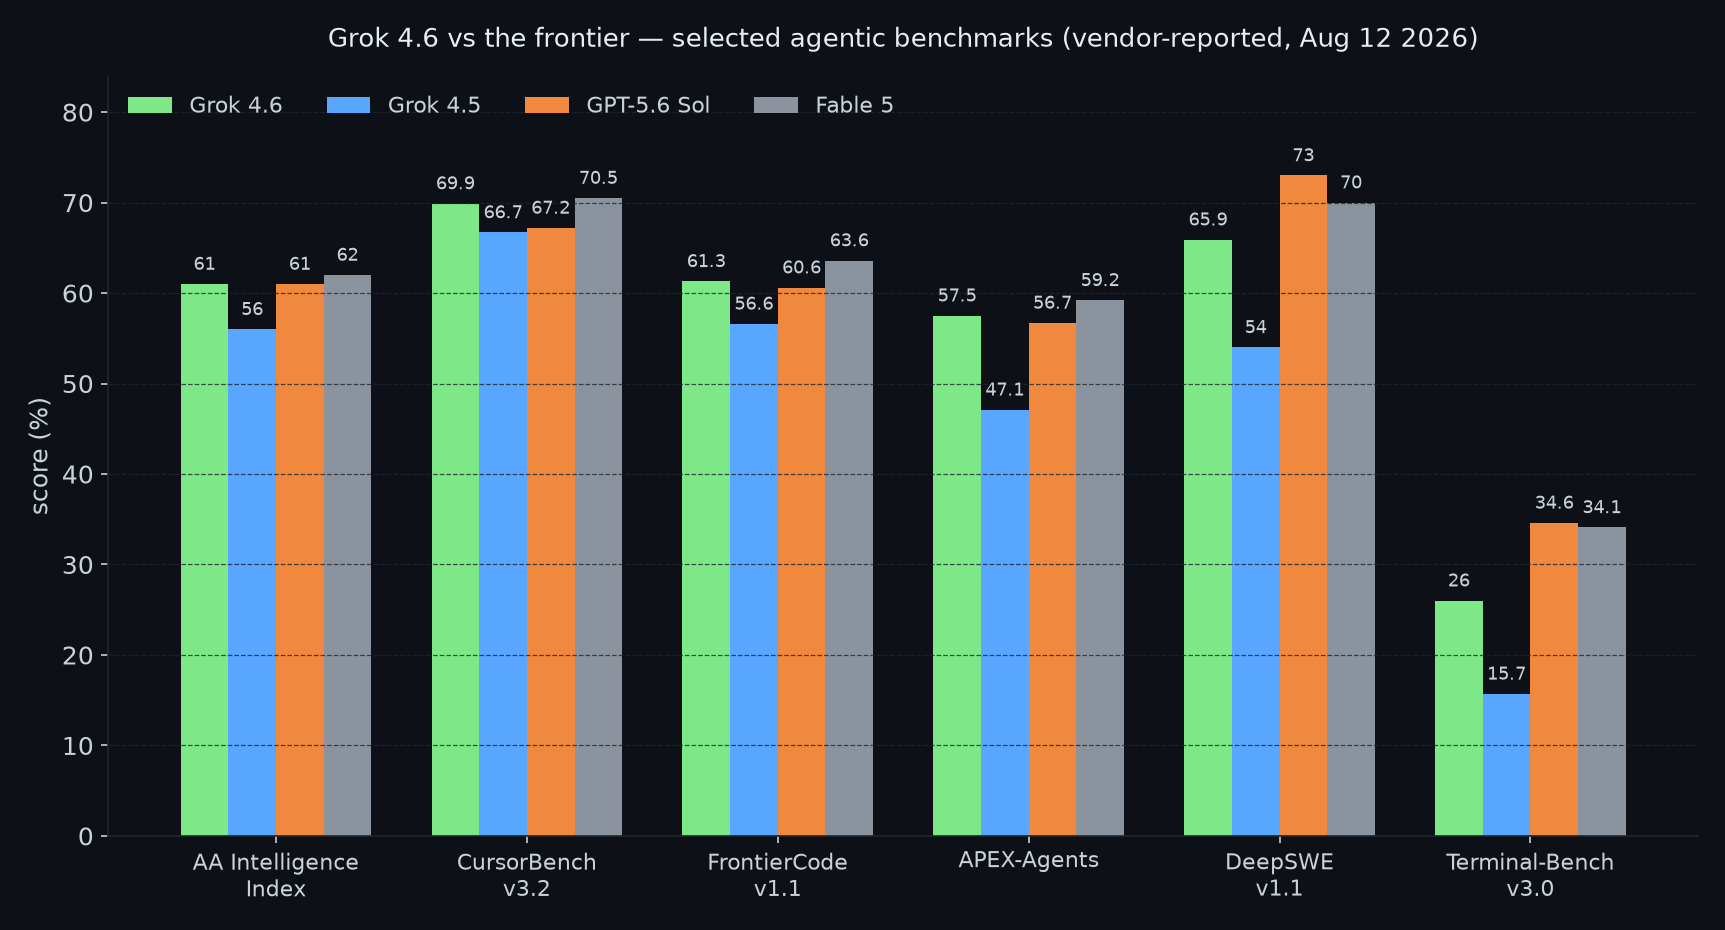
Grok 4.6 vs 4.5 vs GPT-5.6 Sol vs Fable 5 — selected agentic benchmarks (vendor-reported)
The headline holds up: on the AA Intelligence Index — a composite of nine benchmarks — 4.6 really does match GPT-5.6 Sol (61). It beats both GPT-5.6 Sol and Fable 5 on GDPVal-AA v2 and the Harvey legal benchmark, and it beats GPT-5.6 Sol on CursorBench v3.2 — though Fable 5 edges it there, 70.5% to 69.9%.
But it's no clean sweep. On DeepSWE v1.1 (65.9% vs 73%) and especially Terminal-Bench v3.0 (26% vs 34.6%), the harder agentic-coding evals, GPT-5.6 Sol still wins clearly — and SpaceXAI isn't hiding those numbers.
And the jump from 4.5 is bigger than the +5 index points suggest. Look at APEX-Agents (47.1% → 57.5%) and DeepSWE (54% → 65.9%): the RL work landed where it was aimed, on long-running agentic behavior.
List prices and workload cost
The price stayed exactly where 4.5 left it: $2 per million input tokens, $6 per million output — plus a fast variant at twice the price. Put that next to the models it just benchmarked against: GPT-5.6 Sol lists at $5/$30, and Fable 5 — the one model that actually beats it on CursorBench — at $10/$50. On output tokens, 4.6 costs roughly a fifth of Fable 5. SpaceXAI's whole pitch for this model line is that you don't have to choose between frontier scores and sane bills.
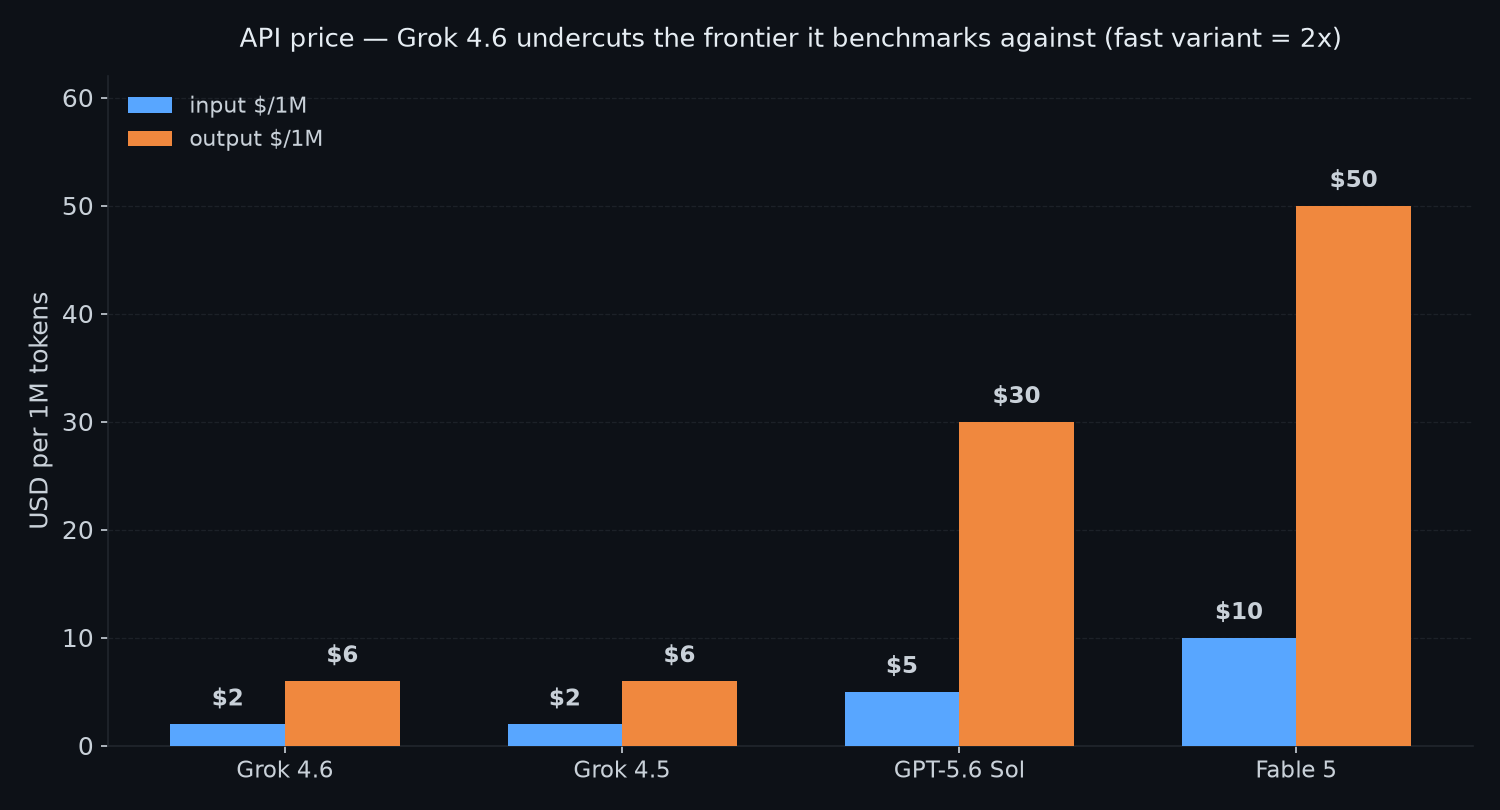
API pricing per 1M tokens (list prices, Aug 2026)
If you're comparing to 4.5's launch: same $2/$6 anchor, same availability playbook. Grok 4.6 is live today in Cursor, Grok Build, Grok Bot, and the API, with OpenRouter, Vercel, and Cloudflare listed as launch partners. And for the first week, Cursor and Grok Build users get 2x included usage — a practical heads-up if you were planning to stress-test it this weekend.
The reported post-training method
The training story is the most interesting part of the release. They gave 4.6 a longer finishing run than 4.5 — more curated data, a better training recipe. Then the clever bit: they had Grok 4.5 itself rewrite the practice answers (the SFT trajectories) across reasoning, agents, STEM, and coding, with model-based checks filtering out the bad traces. The previous model doing homework for the next one is a very 2026 training story, and it's apparently where the agentic gains came from — followed by RL in specialized environments like kernel optimization, web development, and computer-aided design.
The result, per the launch post: stronger first passes on visual and interactive projects, more self-testing on long trajectories (the model checking its own work before moving on), and a special strength at turning a broad product idea into a working first version. That's a very specific claim — give it a vibe, get a working app skeleton — and it reads like the team aimed 4.6 squarely at the Cursor/Grok Build crowd.
Release dates and the 4.7 plan
Context helps here. Musk first teased 4.6 on July 24 ("in 2 weeks"), then refined it on July 27: "the 1.5T model with significantly improved SFT & RL." The release landed today — five days after the "around August 7" target slipped, but inside the "next week" window he'd given on the August 4 earnings call. Grok 4.7 — the 2.1T scale-up, "better in every way, except slightly slower to serve" — is a few weeks behind. None of that changes the model, but it frames what to expect next: 4.6 is the same-size, better-trained refresh, and 4.7 is where the bigger brain shows up.
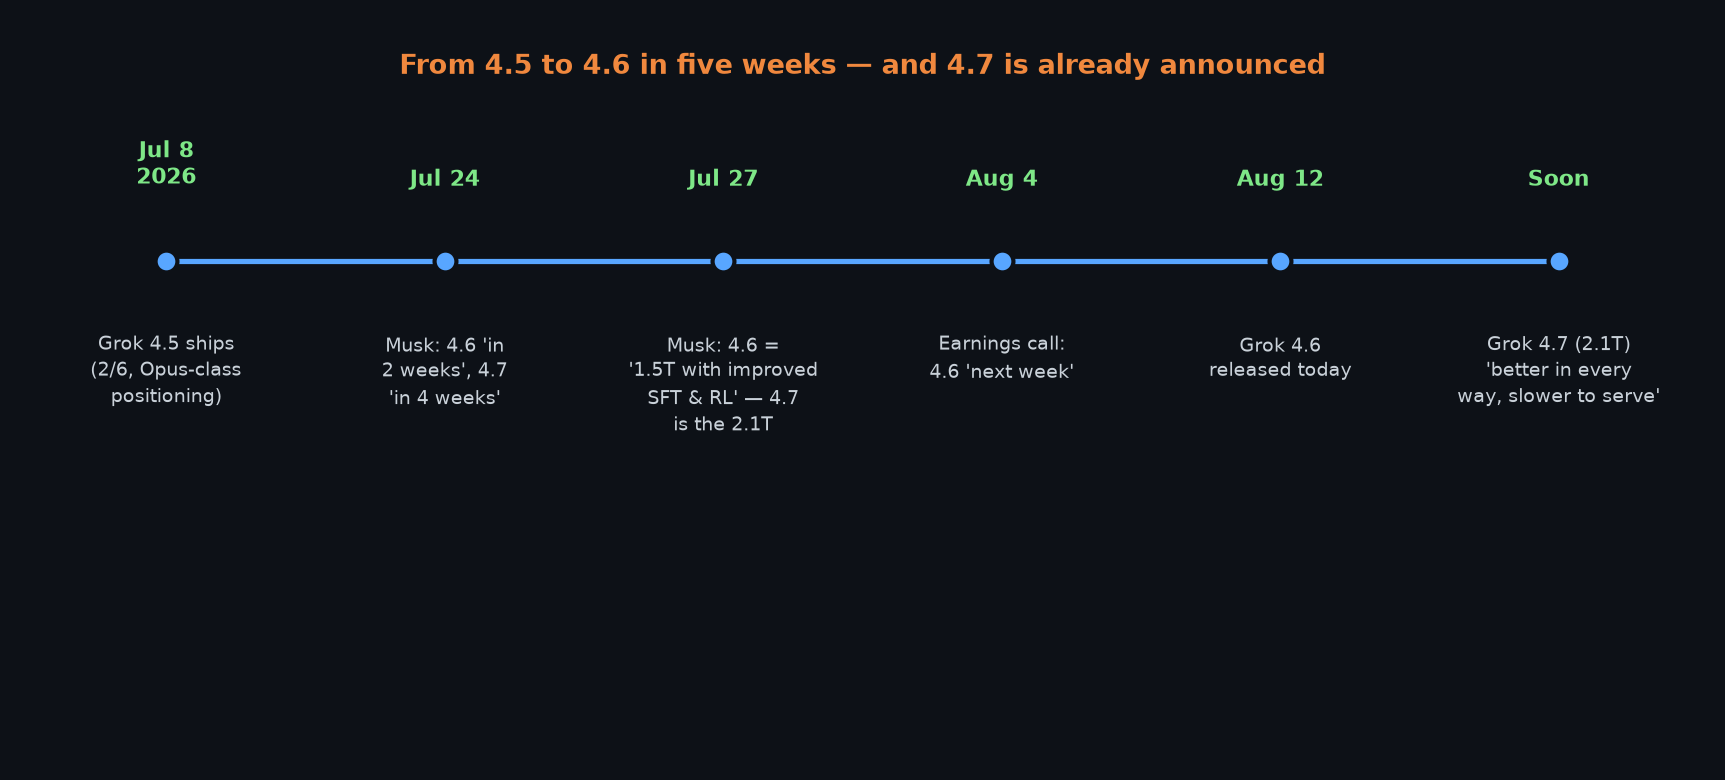
Five weeks from 4.5 to 4.6 — and 4.7 (2.1T) is already teased by Musk
The reported gains include APEX-Agents and DeepSWE, while the cited terminal-coding result remains below GPT-5.6 Sol. A workflow centered on long agent runs may weigh those rows differently from one centered on terminal tasks. The launch card does not establish one model as the better choice for both.
The figures in this launch comparison are attributed to SpaceXAI. A later independent listing should be checked by date, model version and methodology; its appearance cannot be inferred from an announced evaluation schedule.
For a trial, use the same task set and record completed work, latency and billed tokens. Launch-week usage offers and a planned 4.7 release are temporary conditions, so they should be separated from the continuing cost of using 4.6.
Related on this blog: FreeToken Wants to Put Frontier MoE Models on Your Edge Machine · Gemini 3.7 Flash: Half the Price, Still No 3.5 Pro
Links: Official announcement · API models page · Announcement on X · Release-window context
Comments
Post a Comment