Ox Alpha Is Free on OpenCode. Is It MiMo or GLM?
Ox Alpha Is Free on OpenCode. Is It MiMo or GLM?
There is a new model in OpenCode that makes the usual model-name debate feel slightly ridiculous. It is called Ox Alpha. It is free for the next week. It has a million-token context window, accepts images and video, and nobody is officially allowed to tell us who made it.
That last part is why the internet is already guessing MiMo, GLM, MiniMax, Xiaomi, Z.ai — basically every lab with a long-context model and a multimodal demo. Some of those guesses are more interesting than others. None is confirmed.
So I went looking for what is actually documented, what the community is noticing, and where the evidence stops.
What is Ox Alpha?
Ox Alpha is a reasoning model presented for coding, sustained agentic work, production workloads, and workflows that combine text with visual context. OpenRouter lists it under the anonymous provider namespace stealth/ox-alpha. The provider is a third party; OpenRouter says it routes the requests and is not the developer.
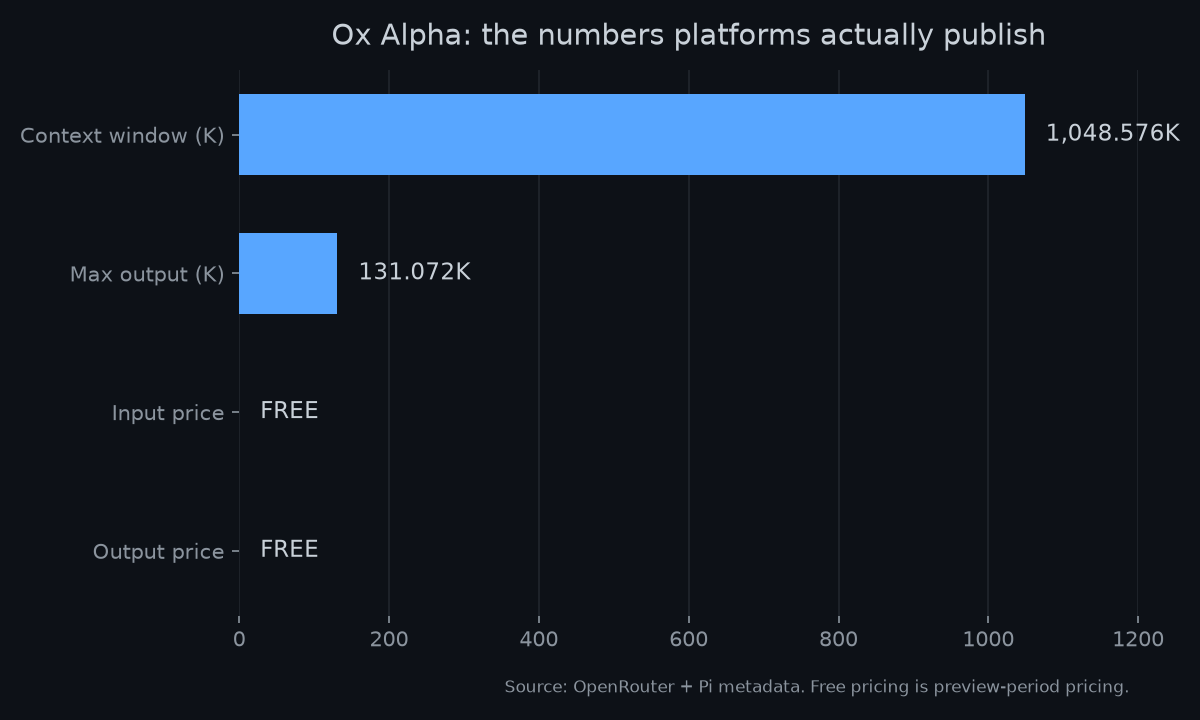
The headline specs are unusually aggressive: 1,048,576 tokens of context, up to 131,072 output tokens, text/image/video input, text output, reasoning, and tool calling. JSON output is supported, although the listing says JSON Schema enforcement is not.
OpenCode's own announcement adds three important claims: zero data retention, generous or near-unlimited limits, and capacity for 100 trillion tokens per day. Those are access and infrastructure claims from OpenCode, not independent throughput measurements.
Why are people saying MiMo or GLM?
Because the shape of the model is a clue, even if it is not proof. A community tester compared Ox Alpha with GLM-5.3 and reported matching context and output limits, similar reasoning modes and API behavior, and matching tokenizer-delta results across a small prompt set. The same post explicitly says this does not prove identical weights.
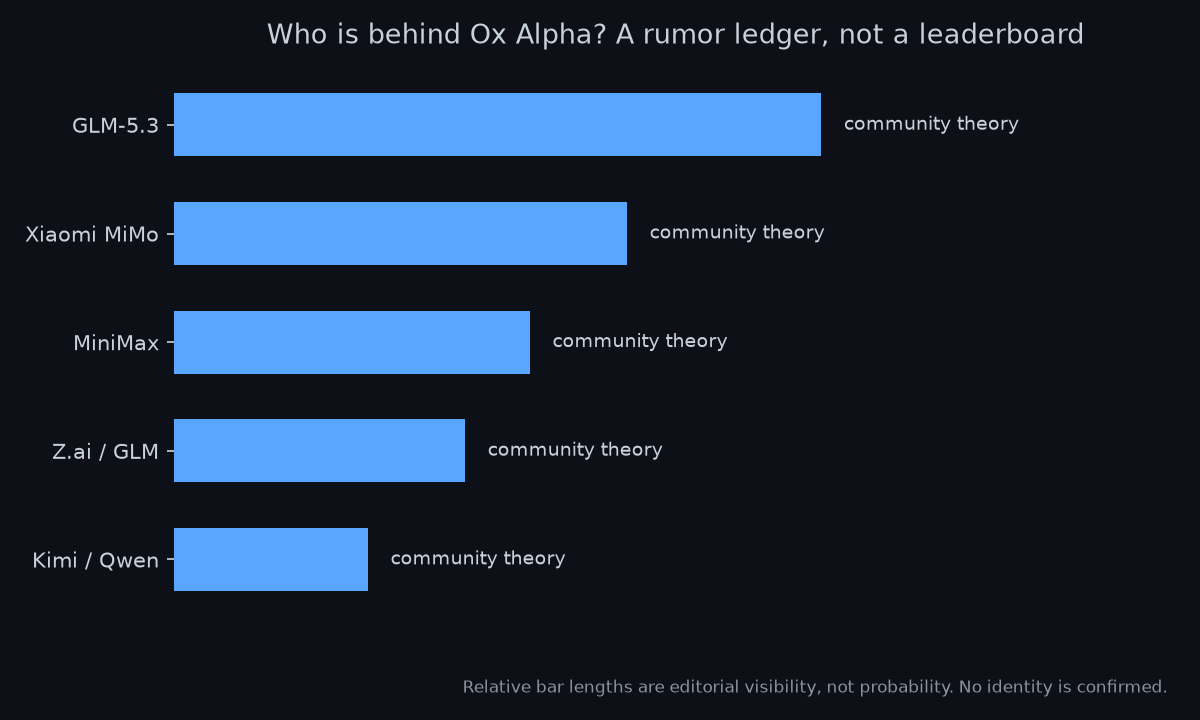
The MiMo theory has a different basis. Reddit users noticed Xiaomi's timing, the multimodal input, and a rumored new MiMo model. MiniMax comes up because its models are known for aggressive pricing and long-context agent use. Z.ai and GLM are mentioned because the reasoning style feels familiar to some testers.
There is even a community claim that Ox Alpha is Hy4. Another user suggested MiniMax M3. This is exactly why I would not put a brand name in the headline as a fact. The evidence is behavioral and circumstantial, not a model card, a tokenizer proof, or a provider admission.
Free, but what is the catch?
For the announced preview window, the token price is $0. OpenRouter lists input, output, and cache reads as free. OpenCode says the model is free for the next week. That is a promotion, not a permanent pricing contract.
The privacy language needs careful reading. OpenCode's X announcement says Zero Data Retention. OpenRouter's model page says prompts and completions are retained by the provider but not used for training, with the remaining conditions governed by the Stealth Model Terms. Those statements may describe different routes or layers, so check the endpoint you are actually using.
My practical rule: do not send private repositories, API keys, customer information, unreleased product code, or anything sensitive until the route and terms are completely clear.
There is also no official benchmark table yet. A handful of screenshots and ten-question comparisons are not a leaderboard. Early Reddit reports are mixed: some users describe excellent screenshot/browser workflows and strong implementation plans; others hit instant rate limits, cut-off reasoning, or availability errors. That is what a free preview under heavy traffic looks like — not a settled performance verdict.
How do you try it in OpenCode?
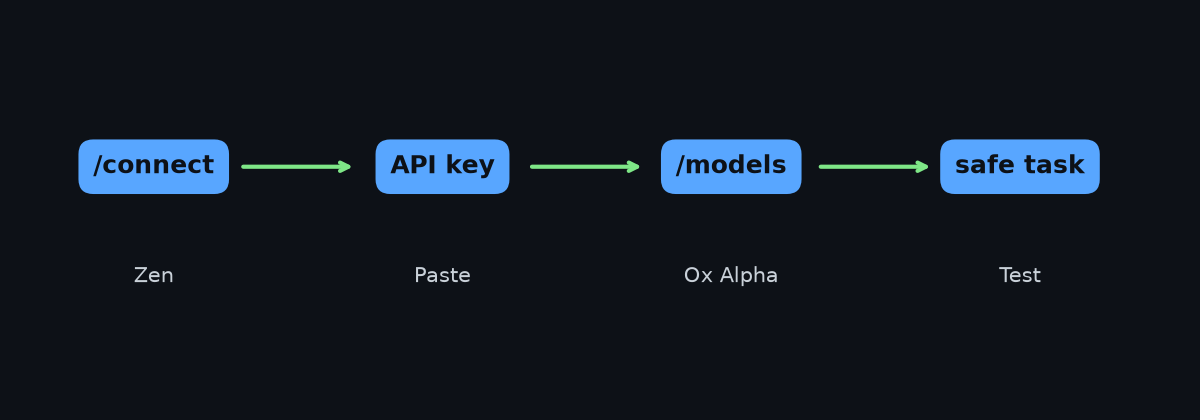
Connect OpenCode Zen, paste your API key, open /models, and select the Ox Alpha free route. The exact temporary model ID may appear as x-preview-f-free in some client metadata, while OpenRouter exposes stealth/ox-alpha. Do not assume those names are interchangeable outside their respective routes.
Start with a task you can verify: inspect a small repository, write tests, fix a contained bug, or analyze a screenshot. Keep a second model ready. If the free route is rate-limited, switch rather than repeatedly hammering it.
My take
Ox Alpha is worth trying, but the useful story is not “we solved the mystery.” The useful story is that an anonymous provider has put a frontier-shaped, multimodal, million-token model in front of developers for a week at zero token cost. That is a very efficient public audition.
My current guess? The GLM-5.3 theory has the cleanest publicly described technical clue because of the reported tokenizer and API similarities. The MiMo theory has the most interesting timing and capability story. MiniMax remains plausible. But “plausible” is not “confirmed,” and the provider may be serving a post-trained variant that does not map neatly to any public model.
Use it while the window is open, run your own small eval, and keep the fallback underneath. If the model turns out to be GLM, MiMo, or something nobody guessed, I'll update this post when the mask comes off.
Related on this blog: Ox Alpha Was GLM-5.3-Flash, Trained on Chinese Chips Alone · 96% to 11%: GLM-5.3-Flash, Uncensored at the Weight Level
Comments
Post a Comment