2026 Local AI Machines Ranked by Value: Which Box Actually Earns Its Price?
2026 Local AI Machines Ranked by Value: Which Box Actually Earns Its Price?
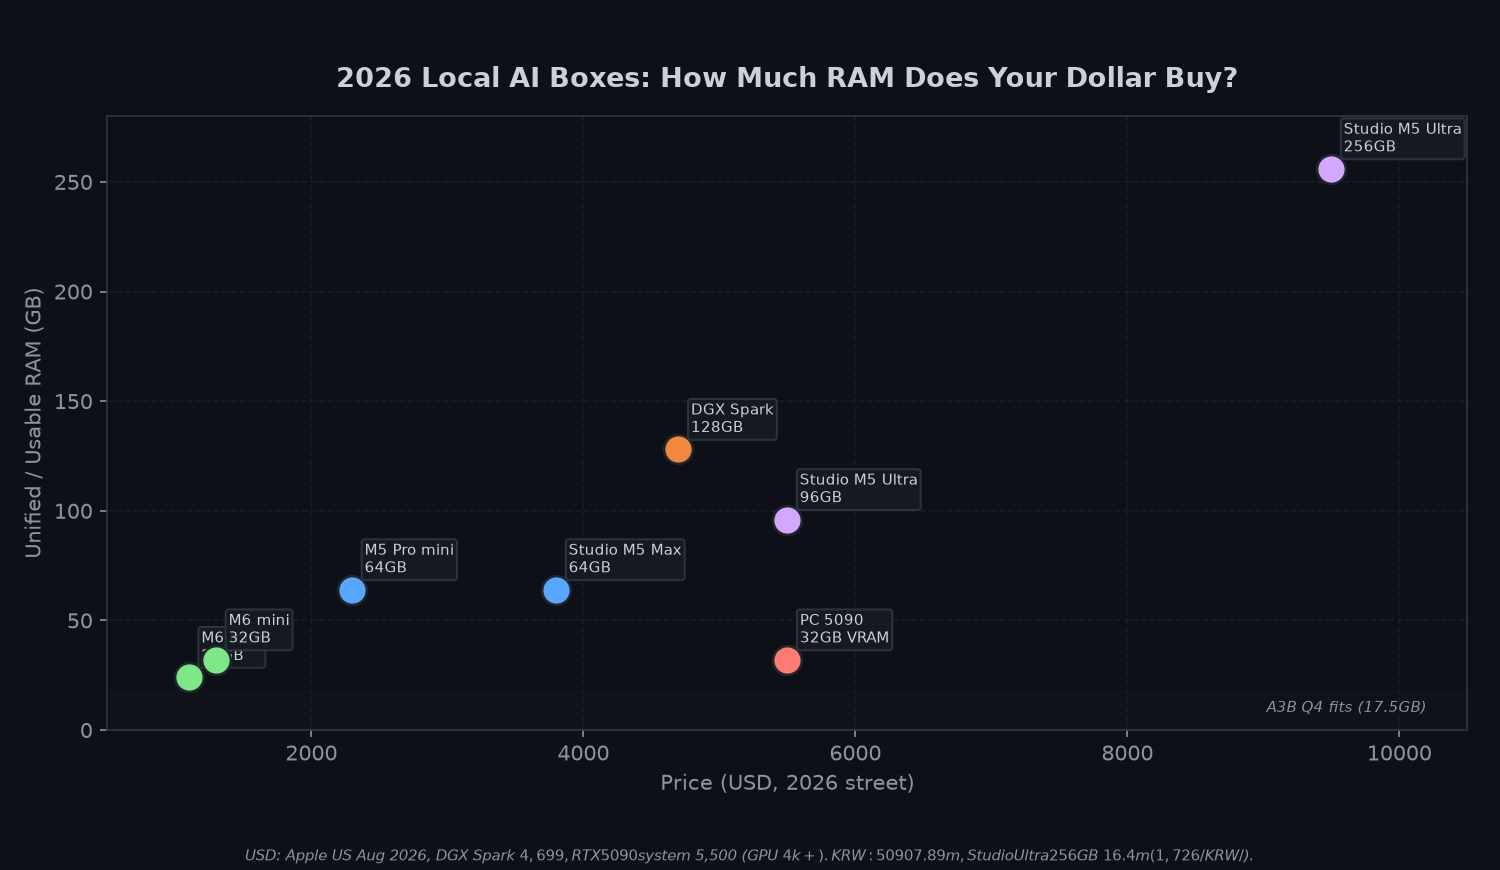
I priced out every box that claims to run open-weight LLMs locally this year — from a $1,099 Mac mini to a $9,499 Mac Studio — and ran the same math on each: can it load the model at all, and how many tokens per second per $1,000 does it actually give you? The ranking flips hard depending on whether you want a fast 35B-A3B or a 284B monster.
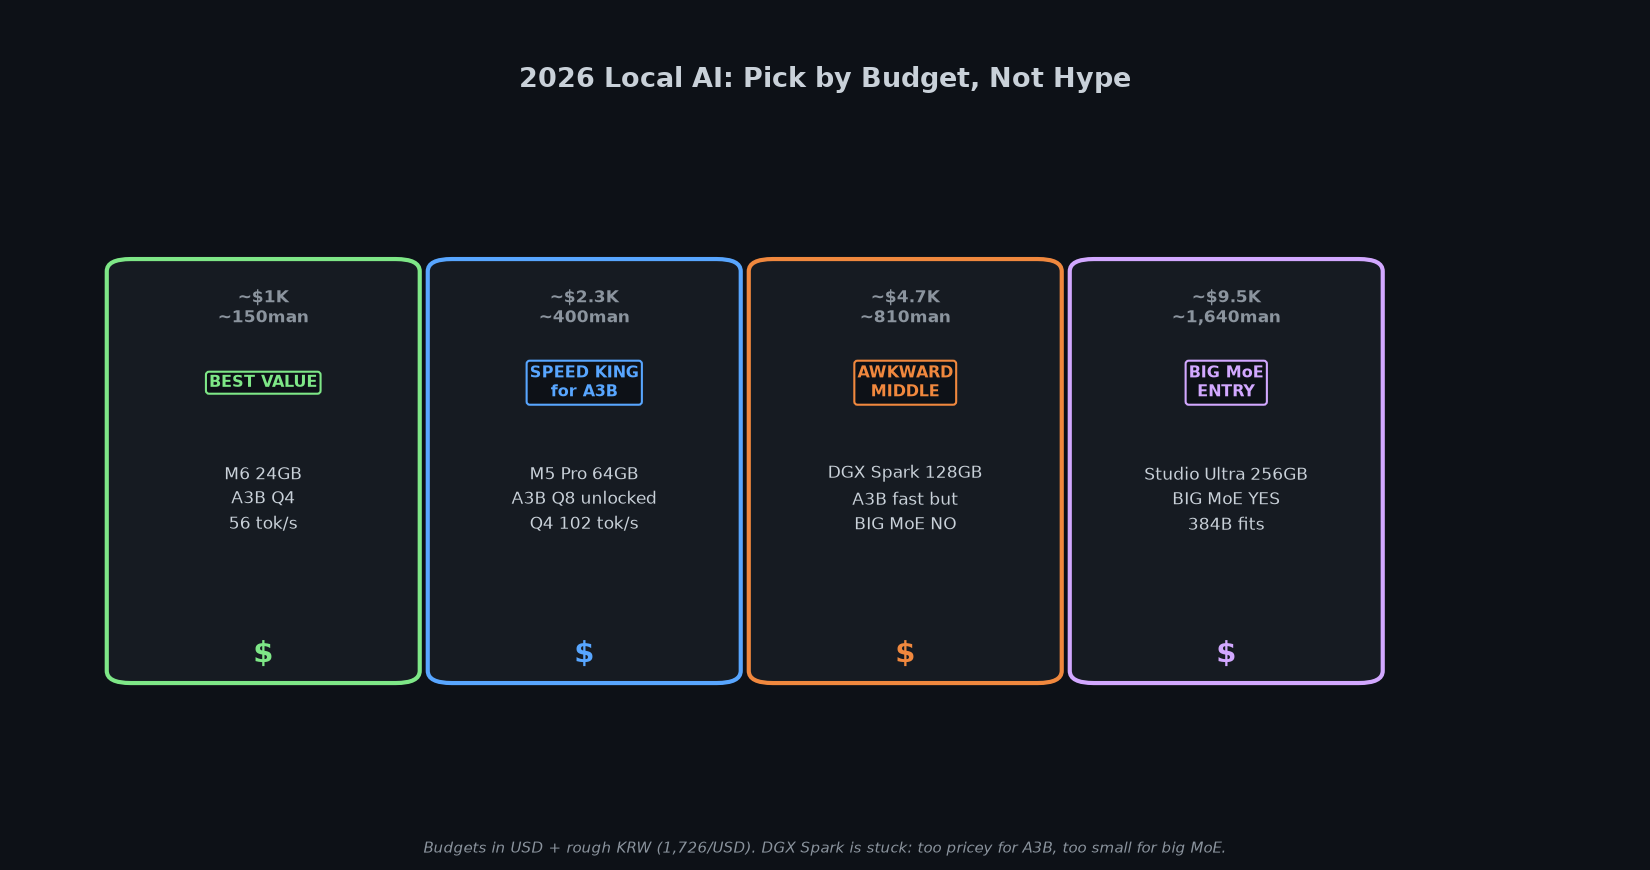
1. Mac mini M6 24GB ($1,099) — best
tok/s per $1,000 for the models most people actually run (Qwen 35B-A3B Q4 at ~56 tok/s = 51 tok/s per $1k).2. Mac mini M5 Pro 64GB ($2,299) — the speed king for that same tier (Q4 ~102 tok/s, and the only mini that unlocks Q8).
3. Mac Studio M5 Ultra 256GB ($9,499) — the only sane entry to big MoE (DeepSeek V4 Flash 284B, GLM-5.3). Expensive, but nothing cheaper fits.
Everything in the middle — DGX Spark at $4,699 — is awkward: too pricey for the small tier, too small for the big tier.
How I ranked: value = realistic tok/s ÷ (price ÷ $1,000) for Qwen3.8-35B-A3B Q4 (the local sweet spot). Big-MoE fit is a binary pass/fail (needs ~170GB). KRW is Danawa street + 1,726 KRW/$ Apple US conversion — check Danawa before you buy, DRAM shortage premiums move weekly.
The Contenders
| Box | RAM | BW | US Price (Aug 2026) | KR Street* |
|---|---|---|---|---|
| Mac mini M6 24GB | 24GB | 170GB/s | $1,099 (16GB $899 + $200) | ~190man |
| Mac mini M6 32GB | 32GB | 170GB/s | $1,299 | ~224man |
| Mac mini M5 Pro 64GB | 64GB | 307GB/s | $2,299 (from $1,699 + RAM) | ~397man |
| Mac Studio M5 Max 64GB | 64GB | 614GB/s | ~$3,800 | ~656man |
| Mac Studio M5 Ultra 96GB | 96GB | ~1.2TB/s | $5,499 | ~949man |
| Mac Studio M5 Ultra 256GB | 256GB | ~1.2TB/s | $9,499 | ~1,640man |
| DGX Spark (GB10) | 128GB | 273GB/s | $4,699 | ~811man |
| PC — RTX 5090 32GB VRAM | 32GB VRAM + host | 1,792GB/s (VRAM) | ~$5,500 (789man card + system) | 789~849man card alone |
*KR Apple effective 1,726 KRW/$. 5090 Danawa Aug 2026: 7,895,000~8,485,000 (PALIT 789man to ASUS TUF 849man), up 40.9% since Jan (Danawa/Videocardz, vendor-reported). DRAM shortage premium is real.
Round 1: The Model Most People Actually Run (Qwen 35B-A3B Q4)
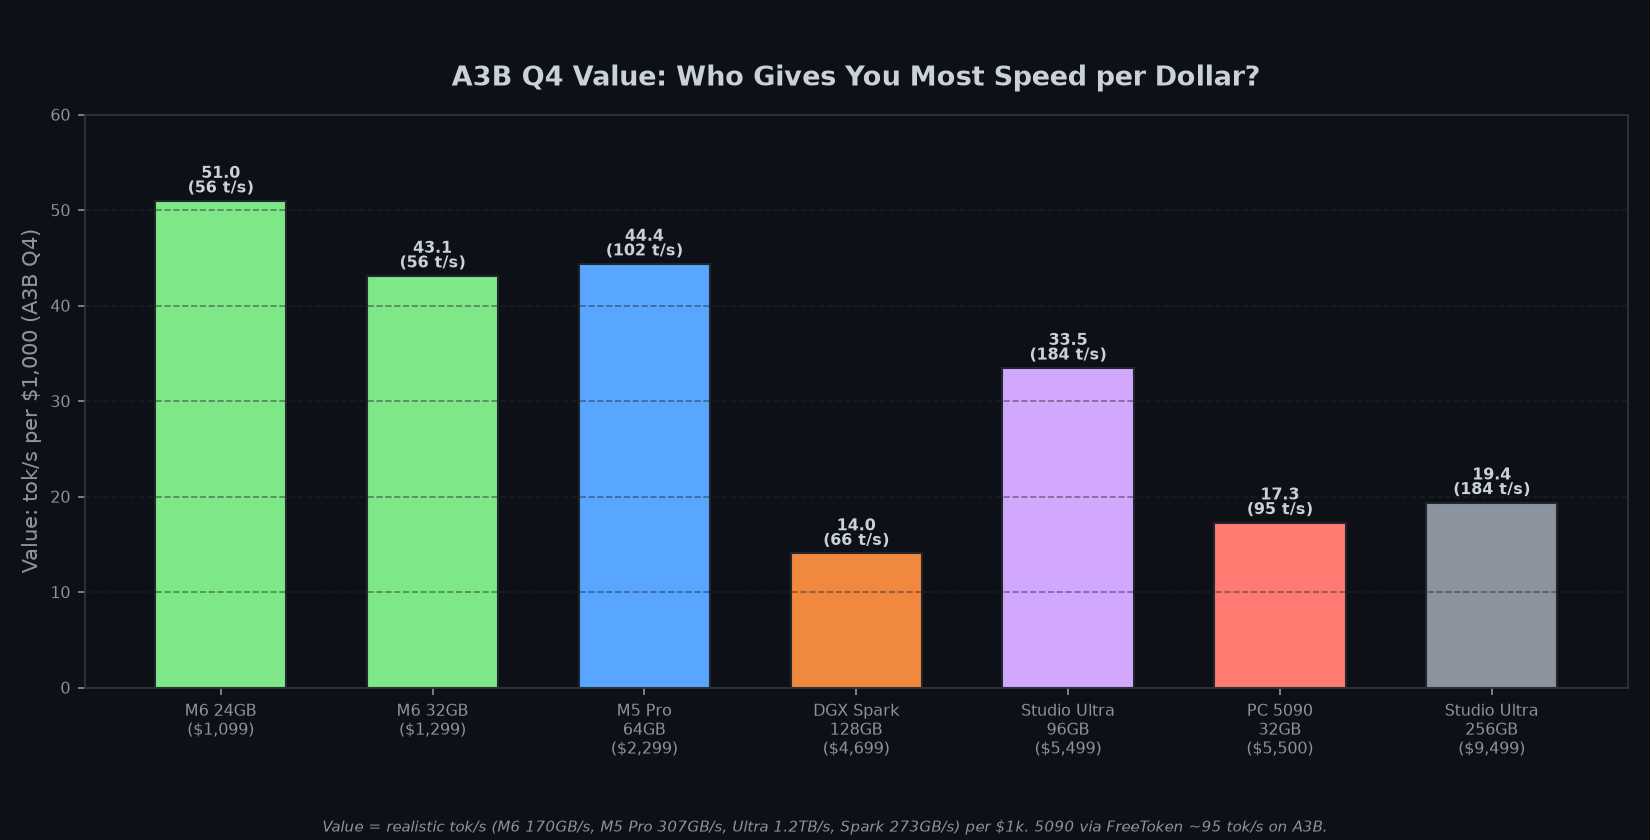
This is the honest workhorse tier — 35B total, 3B active — the model from my previous post that fits a 24GB mini and flies. Here, speed is bandwidth ÷ 1.5GB per token × 0.5, and the mini's unified memory (no PCIe tax) shines.
| Box | A3B Q4 tok/s (est.) | Price | tok/s per $1k | Q8? |
|---|---|---|---|---|
| M6 24GB | ~56 | $1,099 | 51.0 | No (35GB > 24) |
| M6 32GB | ~56 | $1,299 | 43.1 | No |
| M5 Pro 64GB | ~102 | $2,299 | 44.4 | Yes — 51 tok/s |
| DGX Spark 128GB | ~66 | $4,699 | 14.0 | Yes but wasteful |
| Studio Ultra 96GB | ~184 | $5,499 | 33.5 | Yes |
| PC 5090 (FreeToken) | ~95* | ~$5,500 | 17.3 | VRAM 32GB — Q4 yes, Q8 tight |
*5090 A3B via FreeToken/CPU-offload streaming from DDR5 — author estimate. Native unified (Mac) avoids the PCIe hop, so a cheaper mini beats a loaded PC on this tier.
Round 2: The Big MoE Tier (DeepSeek V4 Flash 284B / GLM-5.3 744B)
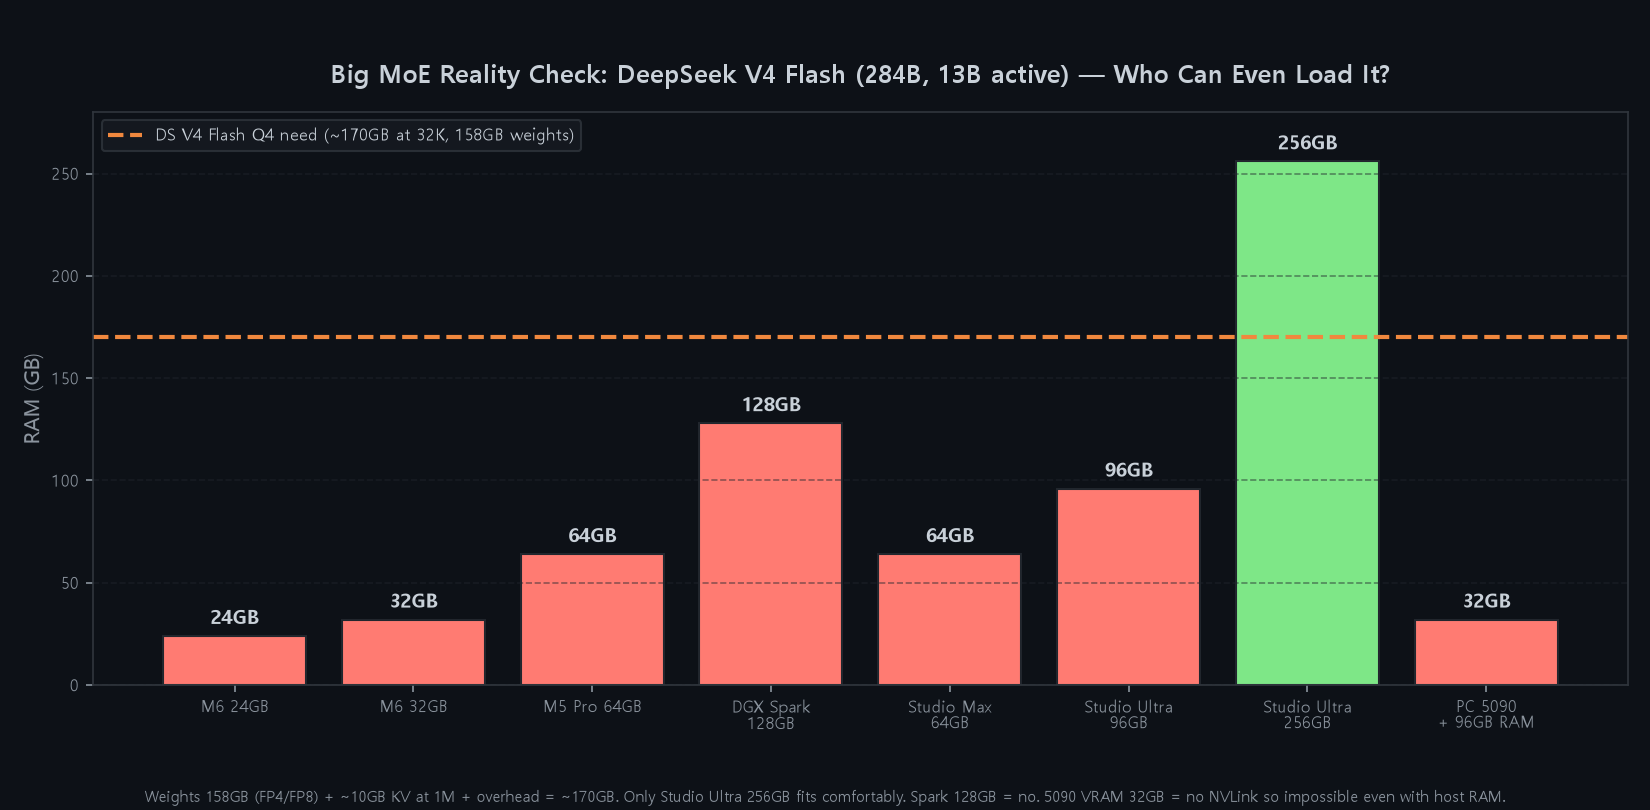
Now flip the table. DeepSeek V4 Flash is 284B total (13B active) — FP4/FP8 weights alone are ~158GB, plus ~10GB KV at 1M = ~170GB to actually use it. GLM-5.3 is heavier. Suddenly "cheap" is irrelevant — if it doesn't fit, it's zero tok/s.
| Box | Fits DS V4 Flash? | Why / Speed if it did |
|---|---|---|
| M6 24/32GB, M5 Pro 64GB, Max 64GB, Spark 128GB | ❌ No | 24–128GB < 170GB — won't load. Zero. |
| Studio Ultra 96GB | ❌ No (tight) | 96 < 170 — no, and 96→256 is a $4k jump with no 128/192 tier. |
| Studio Ultra 256GB | ✅ Yes | ~400–700 tok/s realistic at short ctx (8TB/s class effective via HBM), drops ~50% at 1M. Only sane single-box path. |
| PC 4×5090 (128GB VRAM) | ❌ No | 128GB VRAM < 158GB and no NVLink to pool — still spills to slow PCIe. Even a Threadripper 256GB host + 5090 offload does ~10–25 tok/s vs Ultra's 45–70. |
| DGX Spark ×2 cluster | ⚠️ With hacks | Community Dwarf Star engine does 2× Spark — impressive but not a single-box experience. |
The Full Ranking (by what you actually want to run)
| Rank | Box | Best for | KR Street | Caveat |
|---|---|---|---|---|
| 1 | M6 24GB | A3B Q4 daily driver — agentic coding, chat, 32K ctx | ~190man | Q8 and big MoE no — but you probably don't need them |
| 2 | M5 Pro 64GB | A3B Q8 + max Q4 speed; 64K–128K headroom | ~397man | 2× price for ~1.8× speed on Q4 — buy for Q8, not just Q4 |
| 3 | Ultra 256GB | Big MoE entry (DS V4 Flash / GLM-5.3 2-bit) | ~1,640man | Ultra 96GB at $5,499 can't do big MoE — don't get tricked by the cheaper Ultra |
| 4 | Ultra 96GB | Diffusion (MiniMax H3) full-resident + heavy multitask | ~949man | Great box, wrong for LLM value calc |
| 5 | PC 5090 32GB | Diffusion king (H3 images ~10–60s), plus A3B via offload | card 789man+ | Local LLM value is poor — PCIe tax + 32GB VRAM cap |
| 6 | DGX Spark 128GB | NVIDIA ecosystem, CUDA, dev target | ~811man | Worst value both tiers: $4,699 for 66 tok/s A3B (mini does similar for $1,099) and still can't do big MoE |
When Does Local Pay Off vs $200/mo Cloud?
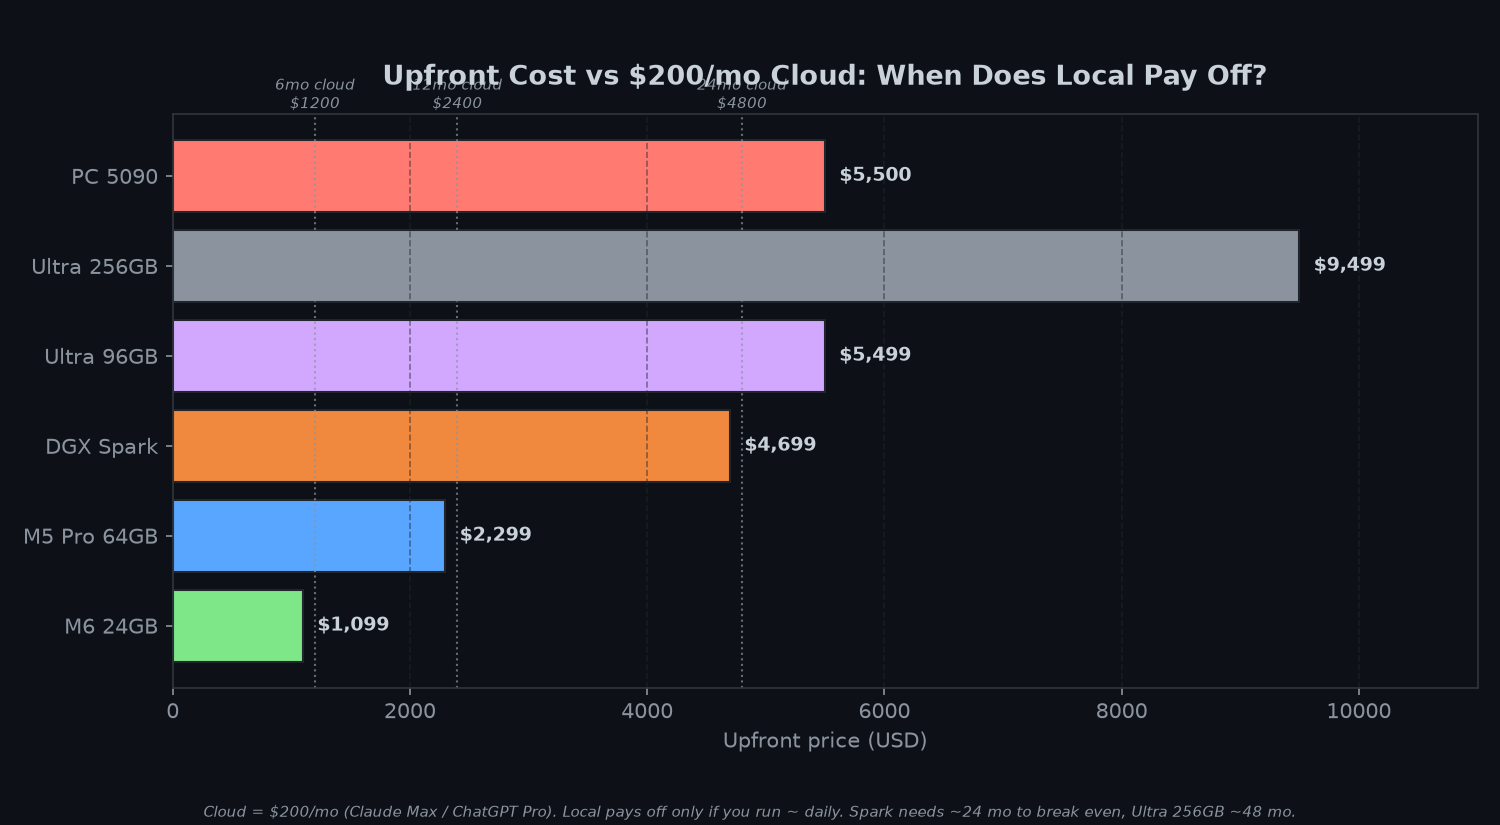
Forbes did the same math on the Ultra launch: Ultra 256GB at $9,499 needs 4.2 years to pay back a $200/mo Claude Max/ChatGPT Pro sub at daily use. M6 24GB pays back in ~5.5 months — that's the value gap. If you only run a few hours a week, rent (or a $5/mo API) wins.
My take — three budgets, three answers
~200man budget (most readers): Mac mini M6 24GB. Don't overthink it. Run A3B Q4. You'll have the best tok/s per dollar in the market and money left for SSD. 32GB only if you live past 64K context.
~400man and you know you want Q8: M5 Pro 64GB. Q8 is slower than Q4 on the same chip (51 vs 102), so buy it for quality, not speed.
You need DS V4 Flash / GLM-5.3: Save for the Ultra 256GB ($9,499 / ~1,640man). There's no cheaper single-box that fits. Don't buy the $5,499 Ultra 96GB thinking you "almost" fit — you don't, and Apple has no 128/192 tier. Two Sparks don't fix it cleanly either.
And skip the Spark for pure value — it's a dev board for the NVIDIA ecosystem, not a value play. In 2026's DRAM shortage, Apple silicon's unified bandwidth per dollar still beats it for small MoE, and it still can't do big MoE without a cluster hack.
FAQ
Why not a used M2 Ultra 128GB?
Legit option if you find one near M5 pricing — 800GB/s class and 128GB fits H3 comfortably. But you're still under the 170GB big-MoE line, so it doesn't solve DS V4 Flash. For A3B, a new M6 24GB will be cheaper and ~faster per dollar.
Is the RTX 5090 useless for local LLM?
No — it's the diffusion king (MiniMax H3 5s video ~26min on Ultra vs ~5 min on 5090 streaming). For LLM, it's just poor value in 2026: the card alone is 789man and still needs a 256GB host that pushes the system to 2,200man+ (Danawa host + DRAM premium). A 190man mini beats it on tok/s per $1k for A3B.
What about RTX Spark laptops (N1X) coming this fall?
Still estimates (~$1,799 N1 / ~$2,899 N1X flagship, vendor-reported) with no OEM street price yet and no independent bench. Same 128GB cap as Spark — so it'll sit in the same awkward middle as the desktop Spark for value. Wait for real reviews.
Sources: Apple Newsroom Aug 25 2026 (M5/M6 specs: 170GB/s, 307GB/s, 1.2TB/s; prices $899/$1,699/$2,499/$5,499/$9,499), NVIDIA DGX Spark $4,699 (TechPowerUp Feb 27, vendor-reported), RTX Spark N1/N1X ~$1,799/~$2,899 analyst est (not official, TechInsider), Forbes Aug 25 Ultra 256GB $9,499 payoff math, Danawa Aug 13 2026 5090 40.9% rise + street 7,895,000~8,485,100 (Videocardz/Danawa), models-and-hardware-2026.md (DS V4 Flash 158GB/170GB, A3B 17.5GB/35GB, BW math). All tok/s vendor-reported math with 0.4–0.6 factor, labeled estimate.
Related: Qwen3.8 35B-A3B on a Mac mini: How Much RAM? · Qwen3.8-27B
Published Aug 31, 2026. KR prices re-verify on Danawa day-of-buy. KR prices re-verify on Danawa day-of-buy; DRAM shortage moves.
Comments
Post a Comment