Qwen Max-0902: Pin the Snapshot Before Comparing
MODELS & COSTS
Qwen Max-0902: Pin the Snapshot Before Comparing
A familiar API model name can hide a changed checkpoint. Qwen's 0902 update reports coding and office-work gains without a new family name. Pinning the snapshot in a task log makes it possible to ask whether the improvement survives your prompts and acceptance tests.
In this article
Same model name, new snapshot: "NOW More Capable -0902." (image: Qwen / @Alibaba_Qwen)
Coding and office-work gains
The August launch was already strong — I flagged TerminalBench and DeepSWE as the highlights, and the open-weights promise landed on schedule (the 2.4T-A95B checkpoint dropped August 12). What 0902 does is fix the embarrassing rows. The agentic terminal coding score that sat at 11.3 in August? 29.0 now. Black-box software replication went from 10.5 to 28.0. Professional job tasks rose from 53.4 to 64.0, and the WorkArena expert Elo climbed 120 points. Multimodal barely moved — this was a coding-and-office post-training, and it shows exactly where it was aimed.
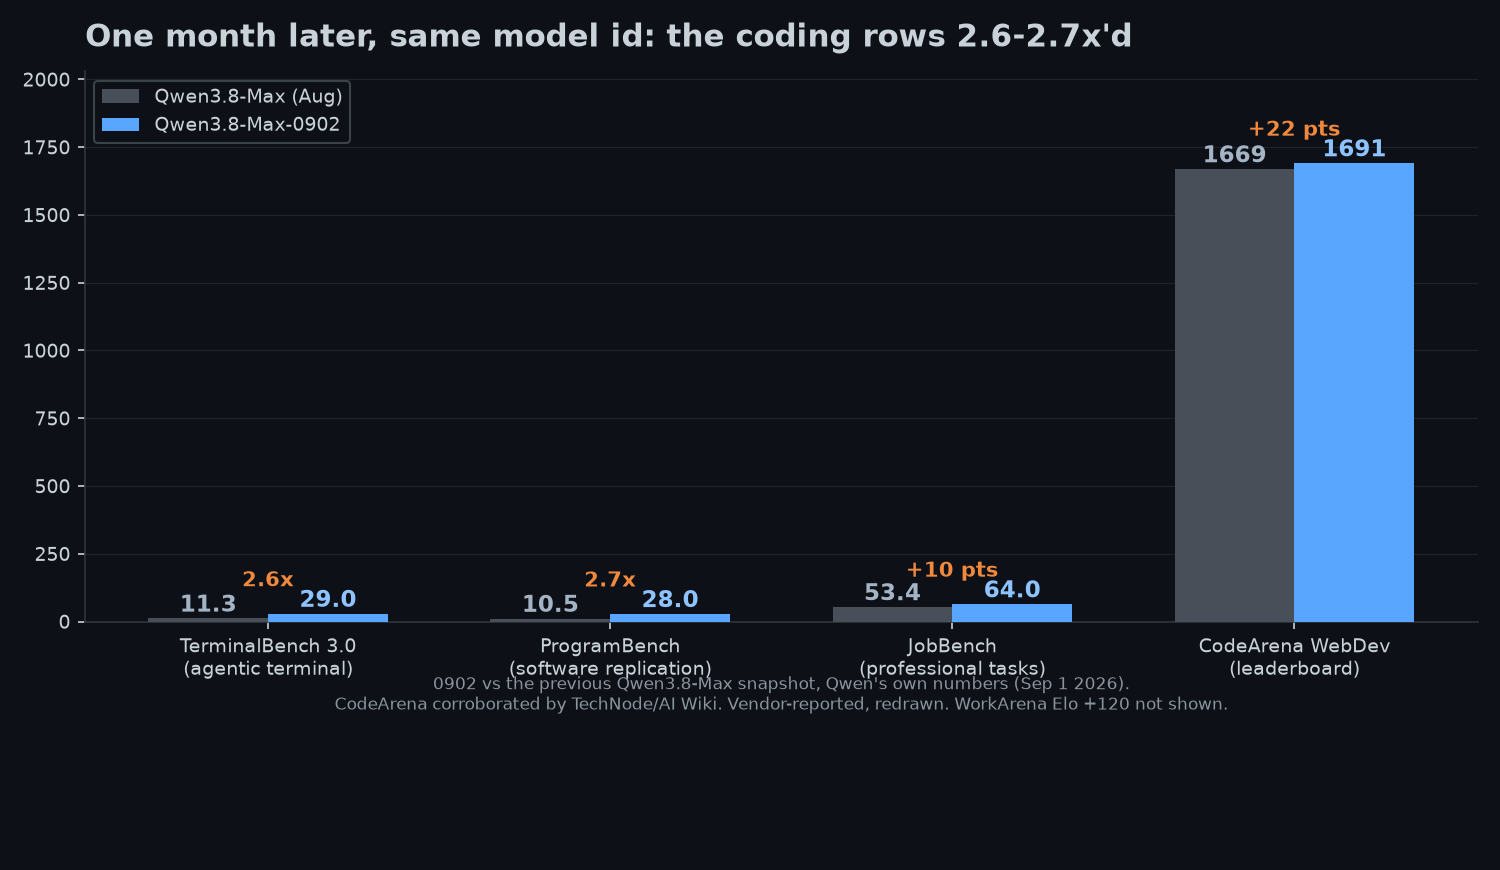
0902 vs the August snapshot, Qwen's own numbers. The rows that were embarrassing doubled and tripled. Vendor-reported, redrawn.
On the public leaderboards it's now first: CodeArena 1691, up 22 points from 1669 — the number-one spot on the front-end coding board, corroborated by TechNode and the live Arena page. A community check called it "almost at the same level as Fable 5 in benchmarks," which is a fair read of the direction of travel even if the exact gap depends on which harness you trust.
Reading Qwen’s comparison table
Qwen published the full comparison table against the previous Max, Claude Opus 5, Fable 5, and GPT-5.6 Sol. Read it carefully and the story splits in two. 0902 leads on repository-level code understanding (SWE-Atlas 66.3, three points over Opus 5 and 27 over Fable 5), SaaS workflow automation (Automation Bench 50.8), and the ML-research engineering row — all real, specific wins. But on the core agentic-coding and office-work rows, Opus 5 is still ahead by 4 to 14 points, and Fable 5.1 shipped the same day without appearing in Qwen's table at all.
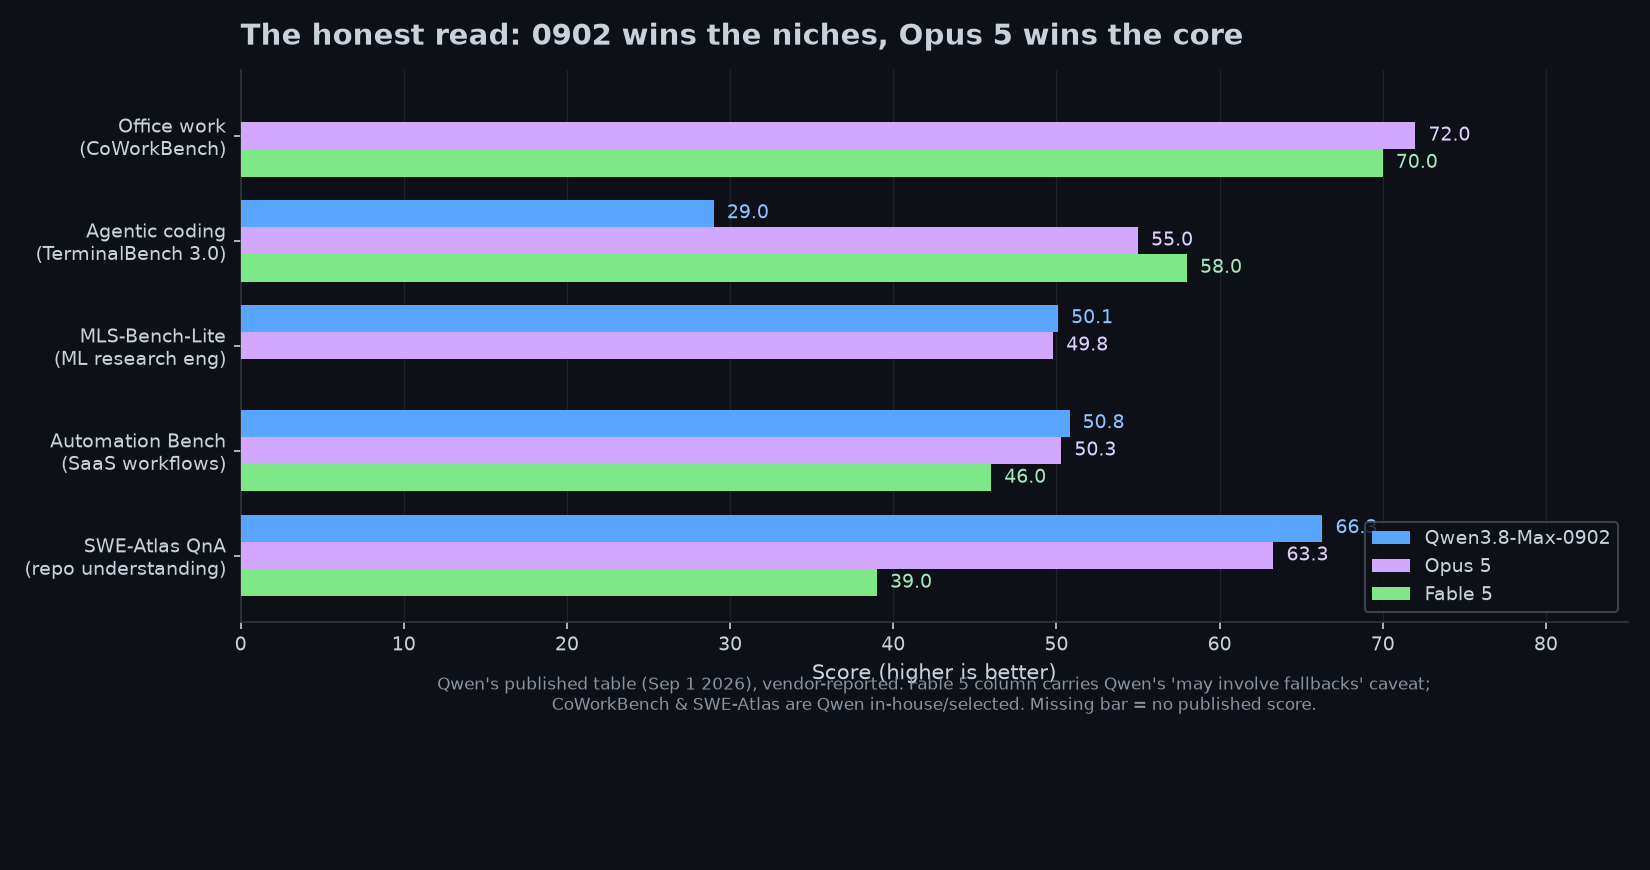
The honest read: 0902 takes the niches, Opus 5 still takes the core rows. Missing bar = no published score. Vendor-reported, redrawn.
Before quoting any of this, read Qwen's own footnotes. The Fable 5 column "may involve fallbacks." Rival TerminalBench scores are "the best published score across harnesses," while Qwen ran its own model with Claude Code at a 10-hour timeout. Three of the benchmarks — QwenSWEBench V2, CoWorkBench, WorkArena — are Qwen's own tests. That doesn't make the table worthless; it makes it directional. The original announcement image is below if you want to squint at the footnotes yourself.
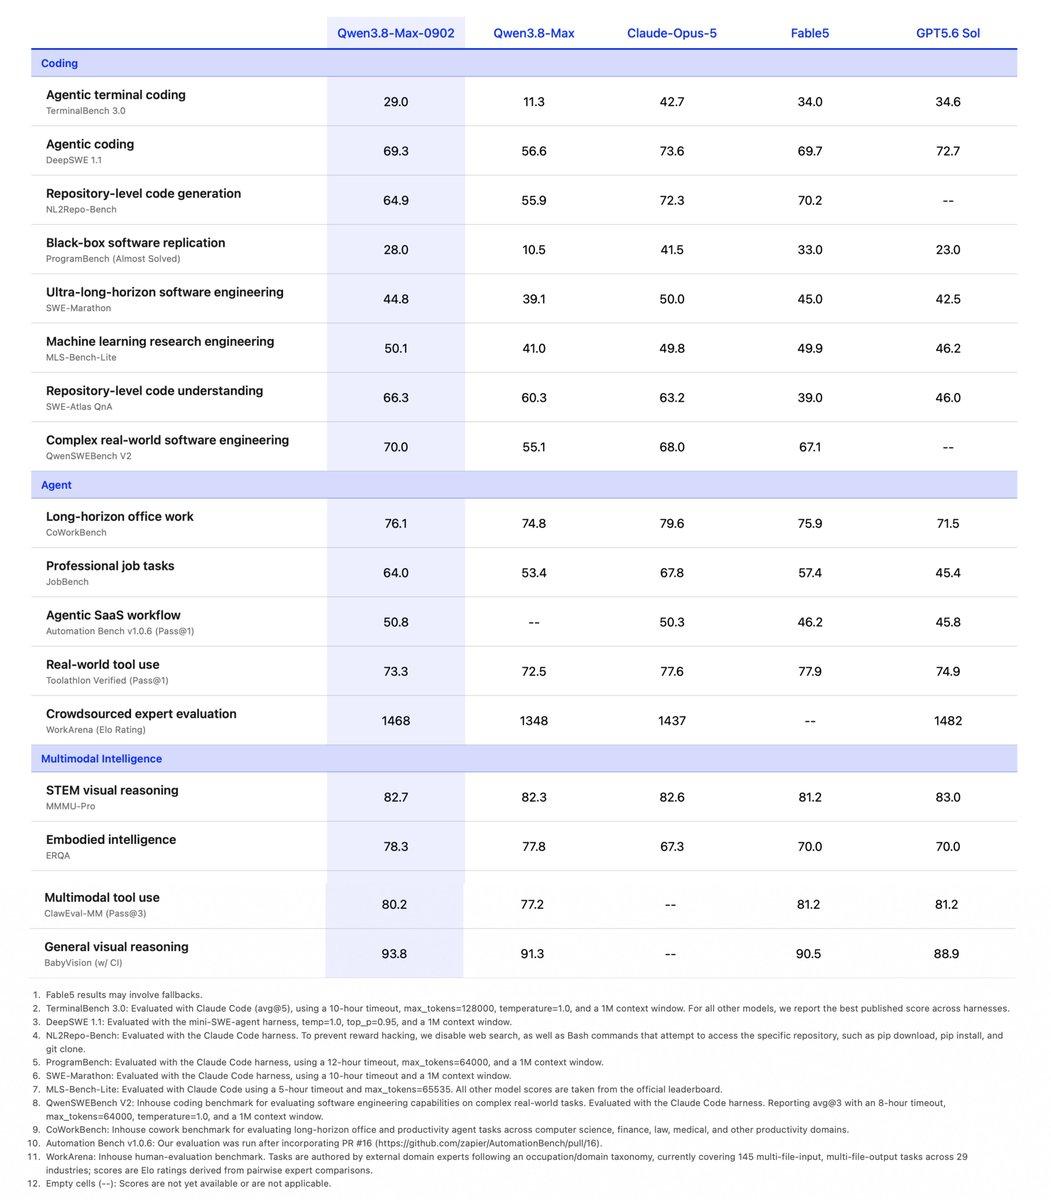
Qwen's official table — 0902 vs previous Max, Opus 5, Fable 5, GPT-5.6 Sol. Note the footnotes. (image: Qwen / @Alibaba_Qwen)
Price and context conditions
The price didn't move — $2 in / $6 out, with cache at $0.25 implicit and $0.17 explicit reads. But the CodeArena value Pareto tells a sharper story: at ~$5 per million tokens blended, 0902 sits at the number-one performance rank with a blended price a quarter of the second-place model's $20/M and under half of third place's $12/M. The cheapest frontier coding model is now also the top-ranked one. That's the kind of number that makes the closed-model pricing conversation uncomfortable.
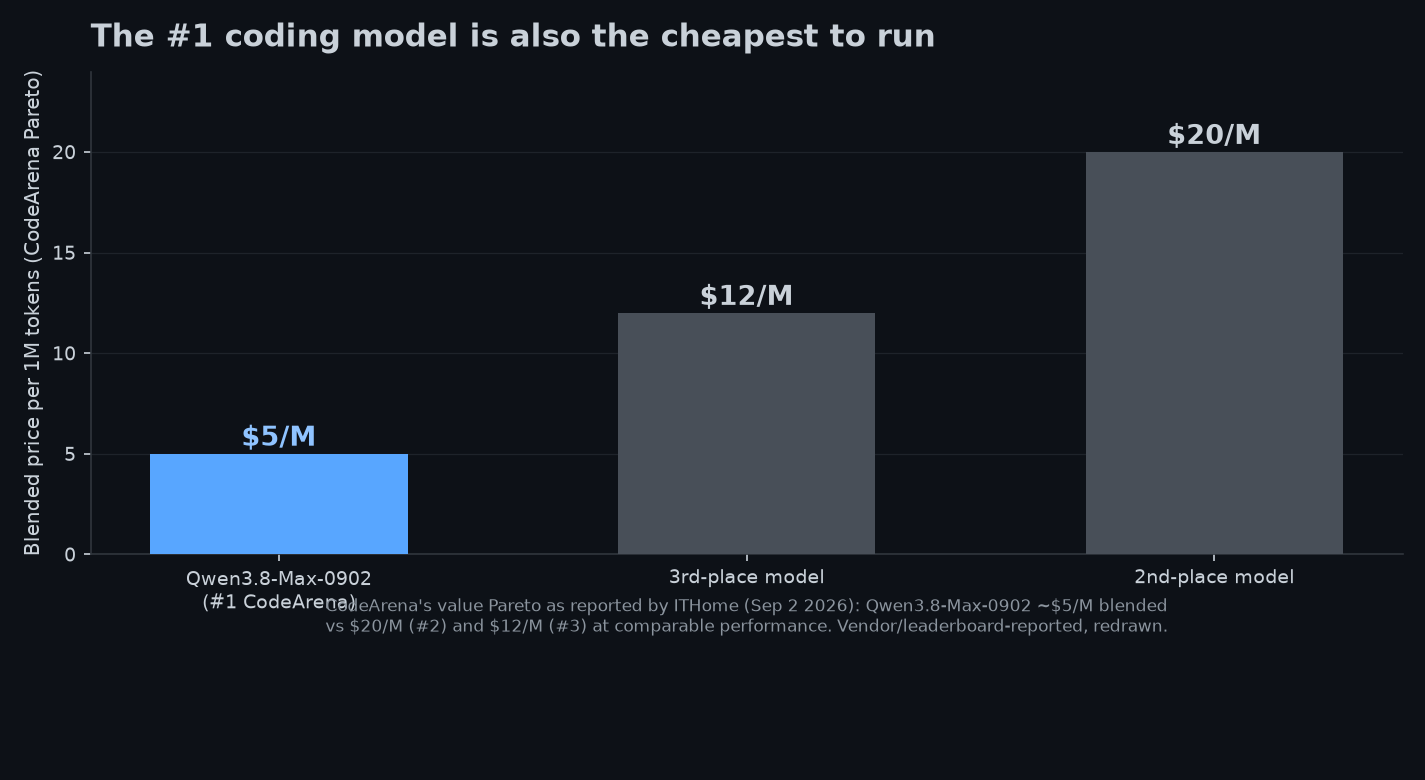
CodeArena's value Pareto: the #1 coding model is also the cheapest to run. Leaderboard-reported, redrawn.
API snapshot versus open checkpoint
No, and that distinction matters. The open-weight Max-class Qwen is the August 12 checkpoint (Qwen3.8-2.4T-A95B, downloadable). 0902 is an API snapshot on QwenCloud with no weights announcement — Qwen's release note describes post-training without saying anything about a downloadable checkpoint. So if you're running the open checkpoint locally or through a third-party host, this upgrade doesn't reach you until Qwen says otherwise. Same story as the August launch in reverse: the hosted model moves monthly, the open weights move on their own schedule.
An existing API user can compare 0902 with the previous snapshot at the same listed token rates. That does not guarantee the same task bill: completion length, retries and tool behavior can change. Keep the prompts and acceptance tests fixed while comparing the update.
For an agent integration, a configurable model choice makes a dated comparison easier to repeat and reverse. Pin the snapshot used in the run log. The API update and the state of the open checkpoint are separate release facts.
Sources: Qwen announcement (X) · QwenCloud model page · TechNode · cellcog analysis · all benchmarks vendor-reported as of September 2, 2026. Related: my original Qwen3.8-Max launch post.
Comments
Post a Comment